# Criston Mascarenhas
> Senior software engineer building reliable products, developer tools, browser automation, SaaS, and native applications.
Canonical Origin: https://criston.dev
## Table of Contents
- [Work | Criston Mascarenhas](#work---criston-mascarenhas)
- [Criston Mascarenhas | Senior Software Engineer](#criston-mascarenhas---senior-software-engineer)
- [About | Criston Mascarenhas](#about---criston-mascarenhas)
- [Myna Notes | Criston Mascarenhas](#myna-notes---criston-mascarenhas)
- [Before Meeting | Criston Mascarenhas](#before-meeting---criston-mascarenhas)
- [Experience | Criston Mascarenhas](#experience---criston-mascarenhas)
- [Criston Mascarenhas | Senior Software Engineer](#criston-mascarenhas---senior-software-engineer)
- [Why We Built Our Own Accessibility Engine (And What "Accuracy" Really Means) | Criston Mascarenhas](#why-we-built-our-own-accessibility-engine--and-what--accuracy--really-means----criston-mascarenhas)
- [Building a Production-Grade Accessibility Scanning Platform | Criston Mascarenhas](#building-a-production-grade-accessibility-scanning-platform---criston-mascarenhas)
- [StackWatch | Criston Mascarenhas](#stackwatch---criston-mascarenhas)
- [A Safe Masked UAT Refresh Pipeline with Dokploy and Greenmask | Criston Mascarenhas](#a-safe-masked-uat-refresh-pipeline-with-dokploy-and-greenmask---criston-mascarenhas)
- [Writing | Criston Mascarenhas](#writing---criston-mascarenhas)
- [Uses | Criston Mascarenhas](#uses---criston-mascarenhas)
- [Building a Scalable Browser Automation Platform for Accessibility Scanning | Criston Mascarenhas](#building-a-scalable-browser-automation-platform-for-accessibility-scanning---criston-mascarenhas)
---
---
title: Work | Criston Mascarenhas
url: https://criston.dev/work
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
Work
Work
Products, open-source tools, and experiments I have designed and built.
## Products
[**A11yInspect**Real-time WCAG accessibility testing inside the browser, on live production pages.Chrome extension · BarrierBreak](https://chromewebstore.google.com/detail/a11yinspect-accessibility/giaolcgipopikbjonacmaokkeiaolmfp) [**A11yNow**Browser-driven automated accessibility engine with versioned WCAG rule mappings.Accessibility testing platform · BarrierBreak](https://www.barrierbreak.com/a11ynow/) [**SemPDF**Zero-dependency TypeScript library for generating, tagging, and editing accessible PDFs.TypeScript PDF library](https://sempdf.criston.dev/) [**Before Meeting**A macOS menu bar app that keeps your next meeting from sneaking up on you.macOS menu bar app](https://criston.dev/products/before-meeting) [**StackWatch**Privacy-first server monitoring and control for Linux boxes, straight from your Android phone.Android server monitoring app](https://criston.dev/products/stackwatch) [**Myna Notes**Live meeting transcription that stays on your Mac and inside an editable note.Private meeting notes · macOS](https://criston.dev/work/myna-notes)
## Open-source & experiments
[**Meerkat** Accessibility audit workspace for consultants that scans client sites, prioritizes WCAG findings, and turns them into shareable reports with clear remediation guidance. Includes real-browser scanning, live-page inspection, public reports, and scheduled monitoring to track accessibility progress over time. Next.js · TypeScript · Playwright · axe-core](https://meerkat.masconics.com) [**Playfleet** Open-source multi-tenant Playwright execution control plane — job queues with tenant concurrency, classified retries (so hard assertion failures don’t thrash the fleet), API keys, per-attempt artifacts, HMAC webhooks, and long-lived agent browser sessions via chromium.connect. Built as a readable TypeScript slice of production browser-automation platforms, not a CI wrapper. TypeScript · Node.js · Hono · Playwright](https://github.com/crstnmac/playfleet) [**CellCron** A durable, self-rescheduling HTTP job runner for celld. Supports cron expressions with IANA timezones, SQLite-backed schedules and run history, exponential retries, bearer-token API protection, and a dashboard for creating, running, and inspecting jobs without relying on in-memory timers. TypeScript · celld · Durable Objects · SQLite](https://github.com/crstnmac/cellcron) [**Browser Pool** A headless browser pool service for taking screenshots with cookie consent handling. Node.js · TypeScript · Playwright · PostgreSQL](https://github.com/crstnmac/browser-pool) [**Site Blocker** A Chrome extension to block distracting websites and improve productivity. React · TypeScript · Chrome Extension](https://github.com/crstnmac/site-blocker-chrome-ext) [**CI Scanner** A fast tree-sitter-based static analysis scanner for CI/CD pipelines with multi-language support, YAML-defined custom rules, and SARIF/JSON outputs for native GitHub and GitLab integrations. Includes CI-friendly exit codes and an optional multi-tenant dashboard server for policy management, cross-repo findings visibility, and GitHub commit status enforcement. Rust · Tree-sitter · CLI · YAML Rules](https://github.com/crstnmac/tree-sitter-ci-scanner)
[contact](https://criston.dev/cdn-cgi/l/email-protection#05666a6b716466714566776c76716a6b2b616073) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Criston Mascarenhas | Senior Software Engineer
url: https://criston.dev
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
Criston Mascarenhas
Senior Software Engineer
I figure out hard problems and turn them into products.
Currently at [BarrierBreak](https://www.barrierbreak.com/), based in Karnataka, India.
[contact](https://criston.dev/cdn-cgi/l/email-protection#d6b5b9b8a2b7b5a296b5a4bfa5a2b9b8f8b2b3a0) [résumé](https://criston.dev/criston-mascarenhas-resume.pdf)
## Selected work
[all work](https://criston.dev/work)
[**A11yInspect**Real-time WCAG accessibility testing inside the browser, on live production pages.Chrome extension · BarrierBreak](https://chromewebstore.google.com/detail/a11yinspect-accessibility/giaolcgipopikbjonacmaokkeiaolmfp) [**A11yNow**Browser-driven automated accessibility engine with versioned WCAG rule mappings.Accessibility testing platform · BarrierBreak](https://www.barrierbreak.com/a11ynow/) [**SemPDF**Zero-dependency TypeScript library for generating, tagging, and editing accessible PDFs.TypeScript PDF library](https://sempdf.criston.dev/) [**Before Meeting**A macOS menu bar app that keeps your next meeting from sneaking up on you.macOS menu bar app](https://criston.dev/products/before-meeting) [**StackWatch**Privacy-first server monitoring and control for Linux boxes, straight from your Android phone.Android server monitoring app](https://criston.dev/products/stackwatch) [**Myna Notes**Live meeting transcription that stays on your Mac and inside an editable note.Private meeting notes · macOS](https://criston.dev/work/myna-notes)
## Writing
[all writing](https://criston.dev/writing)
- [A Safe Masked UAT Refresh Pipeline with Dokploy and GreenmaskJun 18, 2026](https://criston.dev/writing/safe-masked-uat-refresh-pipeline-dokploy-greenmask)
- [Building a Production-Grade Accessibility Scanning PlatformJun 16, 2026](https://criston.dev/writing/building-a-production-grade-accessibility-scanning-platform)
[contact](https://criston.dev/cdn-cgi/l/email-protection#9efdf1f0eafffdeadefdecf7edeaf1f0b0fafbe8) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: About | Criston Mascarenhas
url: https://criston.dev/about
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
About
About
Engineering philosophy, working style, and a little personal context.
- Based in
- Karnataka, India
- Currently
- Senior Software Engineer at BarrierBreak
- Focus
- Product engineering, accessibility, platforms, and developer tools
Recent proof: [Myna Notes](https://criston.dev/work/myna-notes), [A11yNow](https://criston.dev/work), and [SemPDF](https://sempdf.criston.dev/).
## How I build
I like building software where the product, system design, and interface all have to meet in the middle. Sometimes that is a SaaS platform, sometimes a browser extension, sometimes a native app, and sometimes a tool that makes a messy workflow predictable.
I work across the stack because good products rarely live in one layer. I have shipped browser automation, multi-tenant APIs, auth and billing flows, dashboards, PDF tooling, macOS utilities, Android server monitoring, and CI integrations.
I am drawn to problems where developer experience, reliability, and product judgment intersect. I value clear tradeoffs, maintainable systems, and tools that do one thing well.
## Listening
Loading current track…
### Recently Played
[contact](https://criston.dev/cdn-cgi/l/email-protection#a2c1cdccd6c3c1d6e2c1d0cbd1d6cdcc8cc6c7d4) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Myna Notes | Criston Mascarenhas
url: https://criston.dev/work/myna-notes
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
Myna Notes
# Myna Notes
Private meeting notes · macOS
Live meeting transcription that stays on your Mac and inside an editable note.
On-device meeting transcription and note-taking for macOS. Speech is transcribed live — from the microphone, from system audio (the other side of a call), or both — and written directly into the note as you talk. Nothing leaves your computer: ASR runs locally on the Apple Neural Engine.
[Download for macOS](https://github.com/crstnmac/myna-notes/releases/download/v0.1.0/Myna-Notes-macos-arm64.zip)
React · TypeScript · Tauri · Rust · Swift · Core ML · macOS
## Inside the product
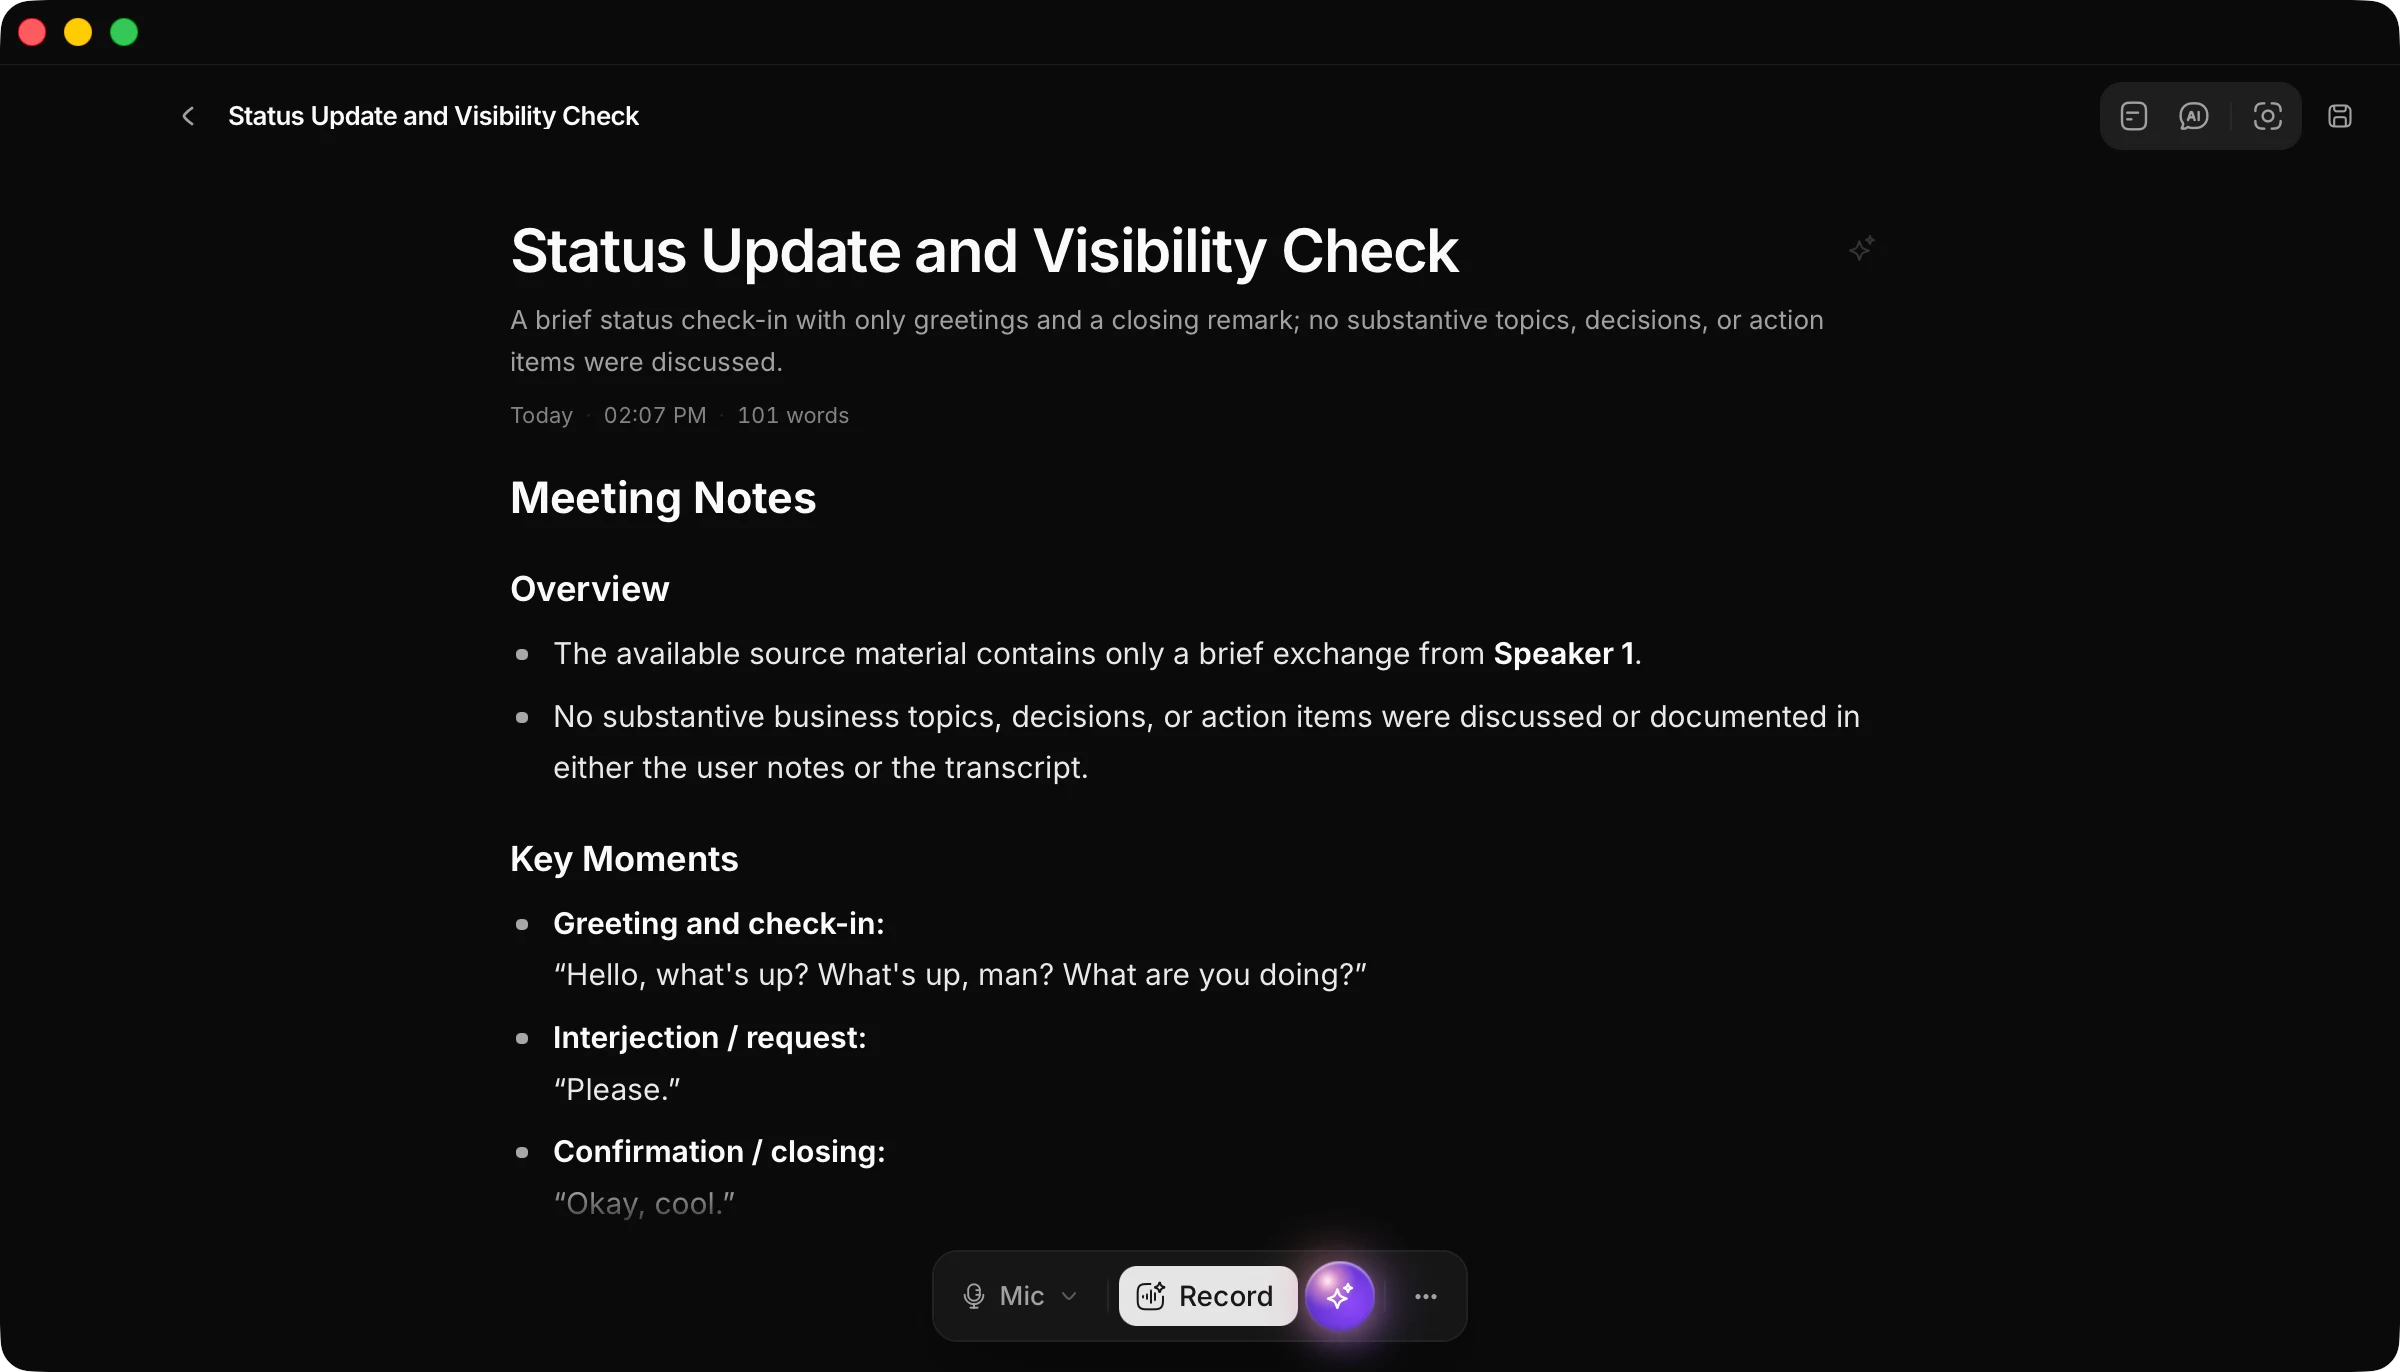***Editable transcript***
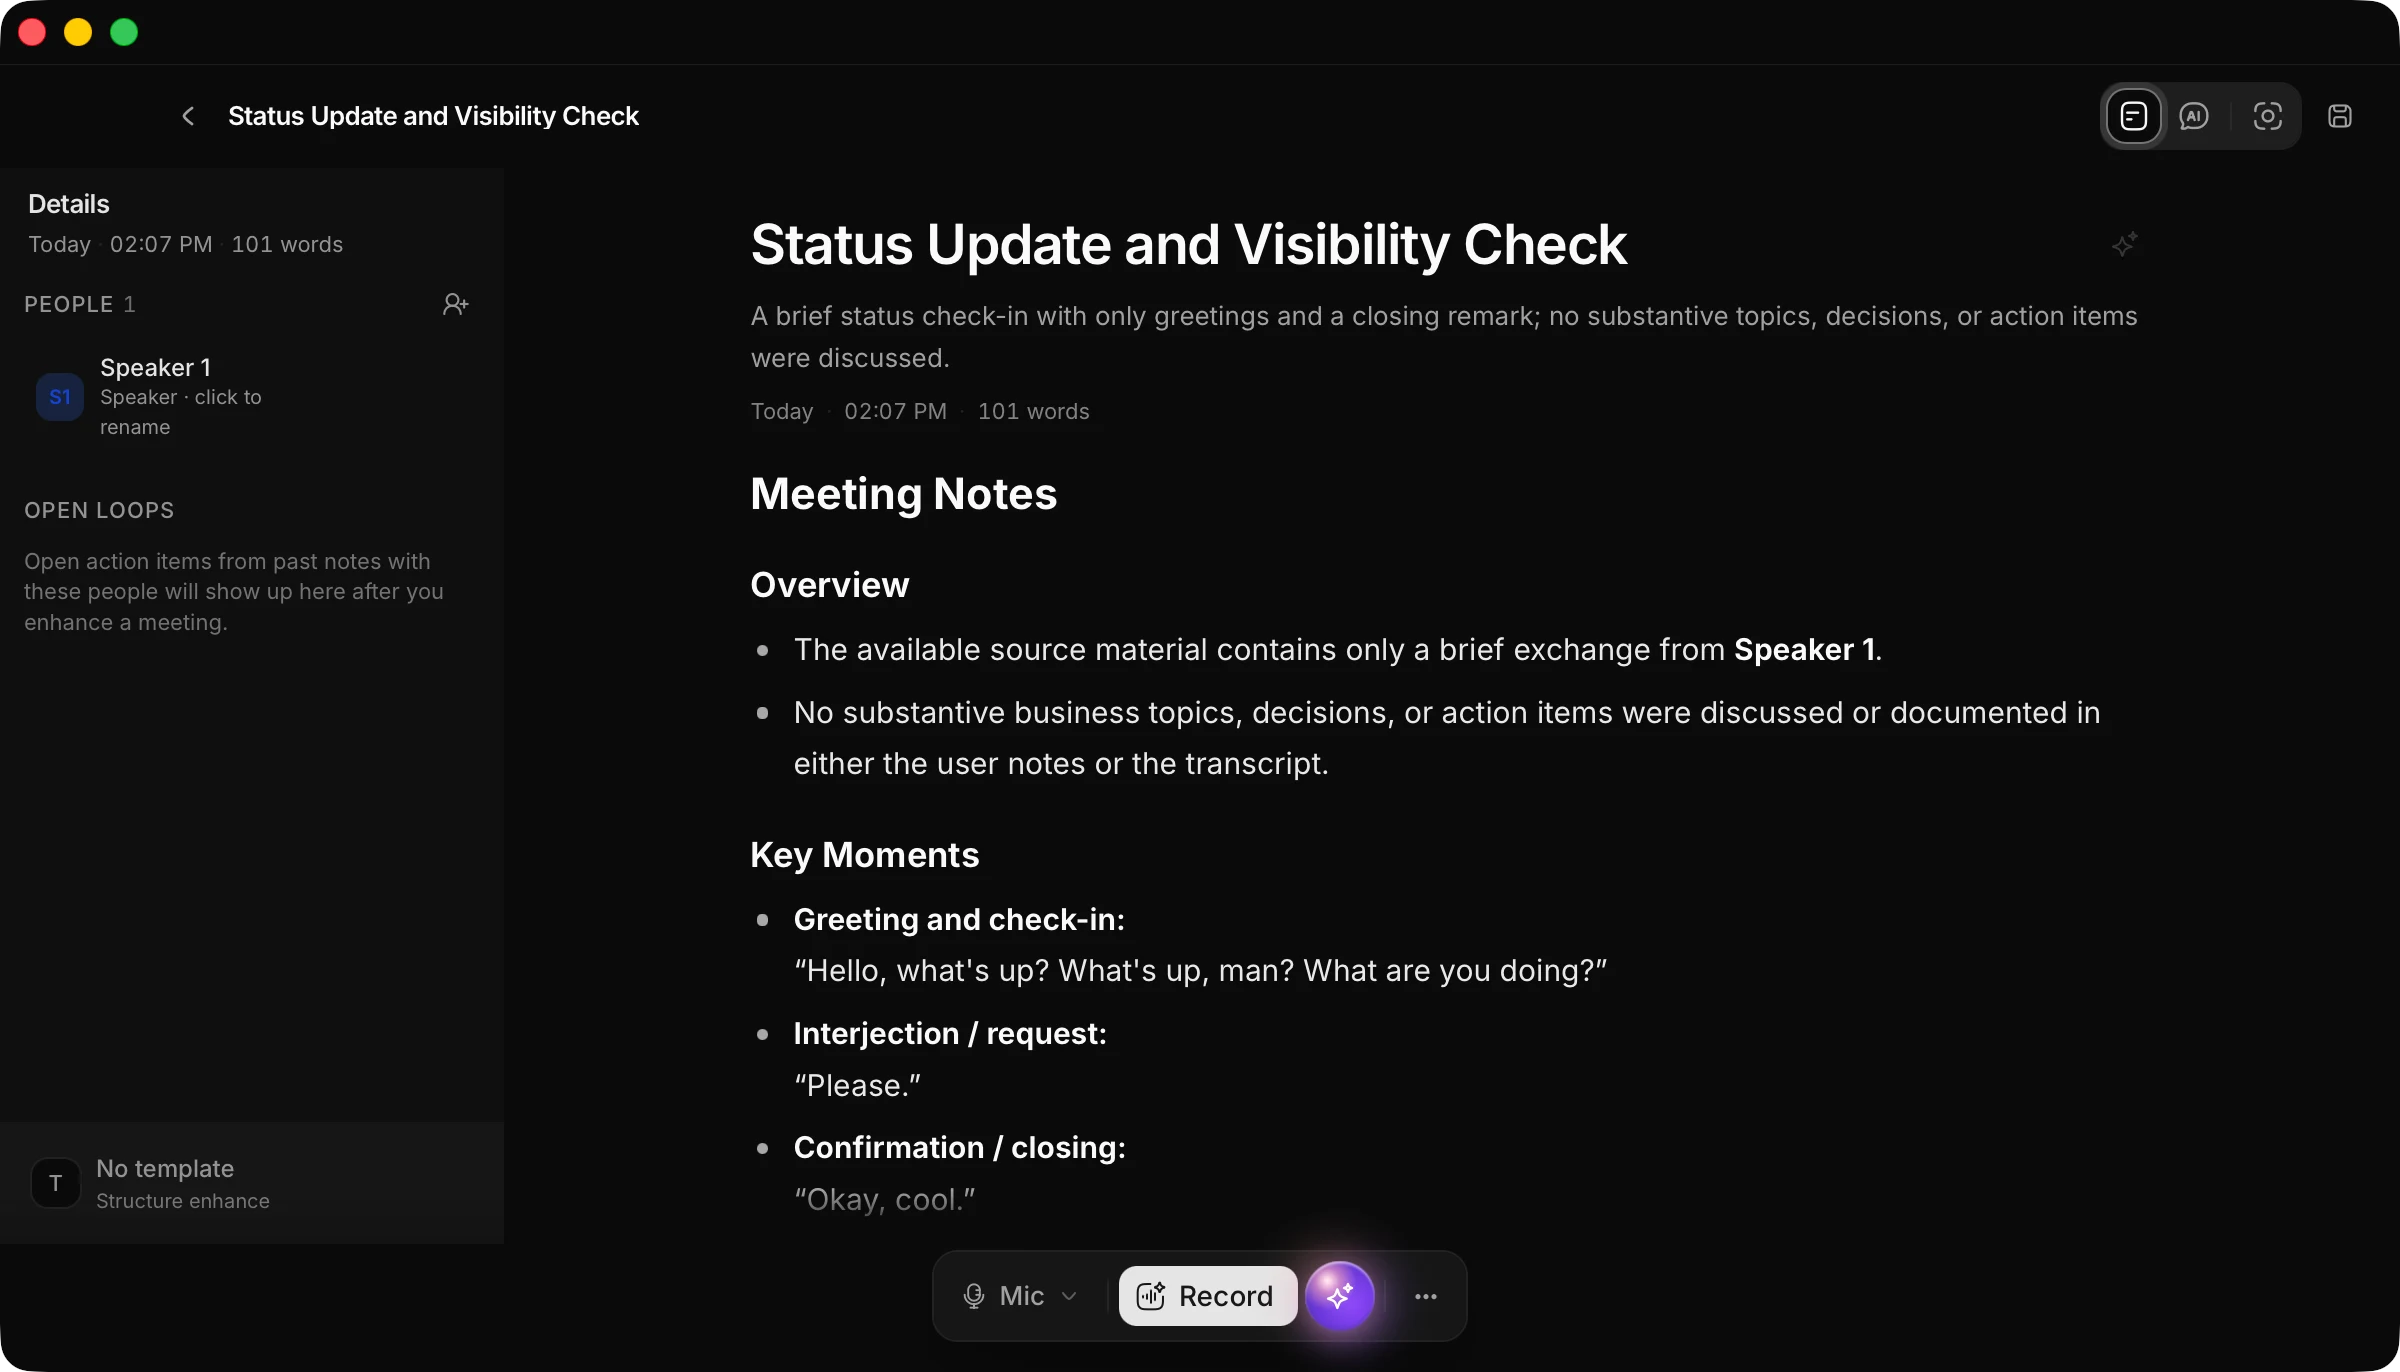***Structured meeting details***
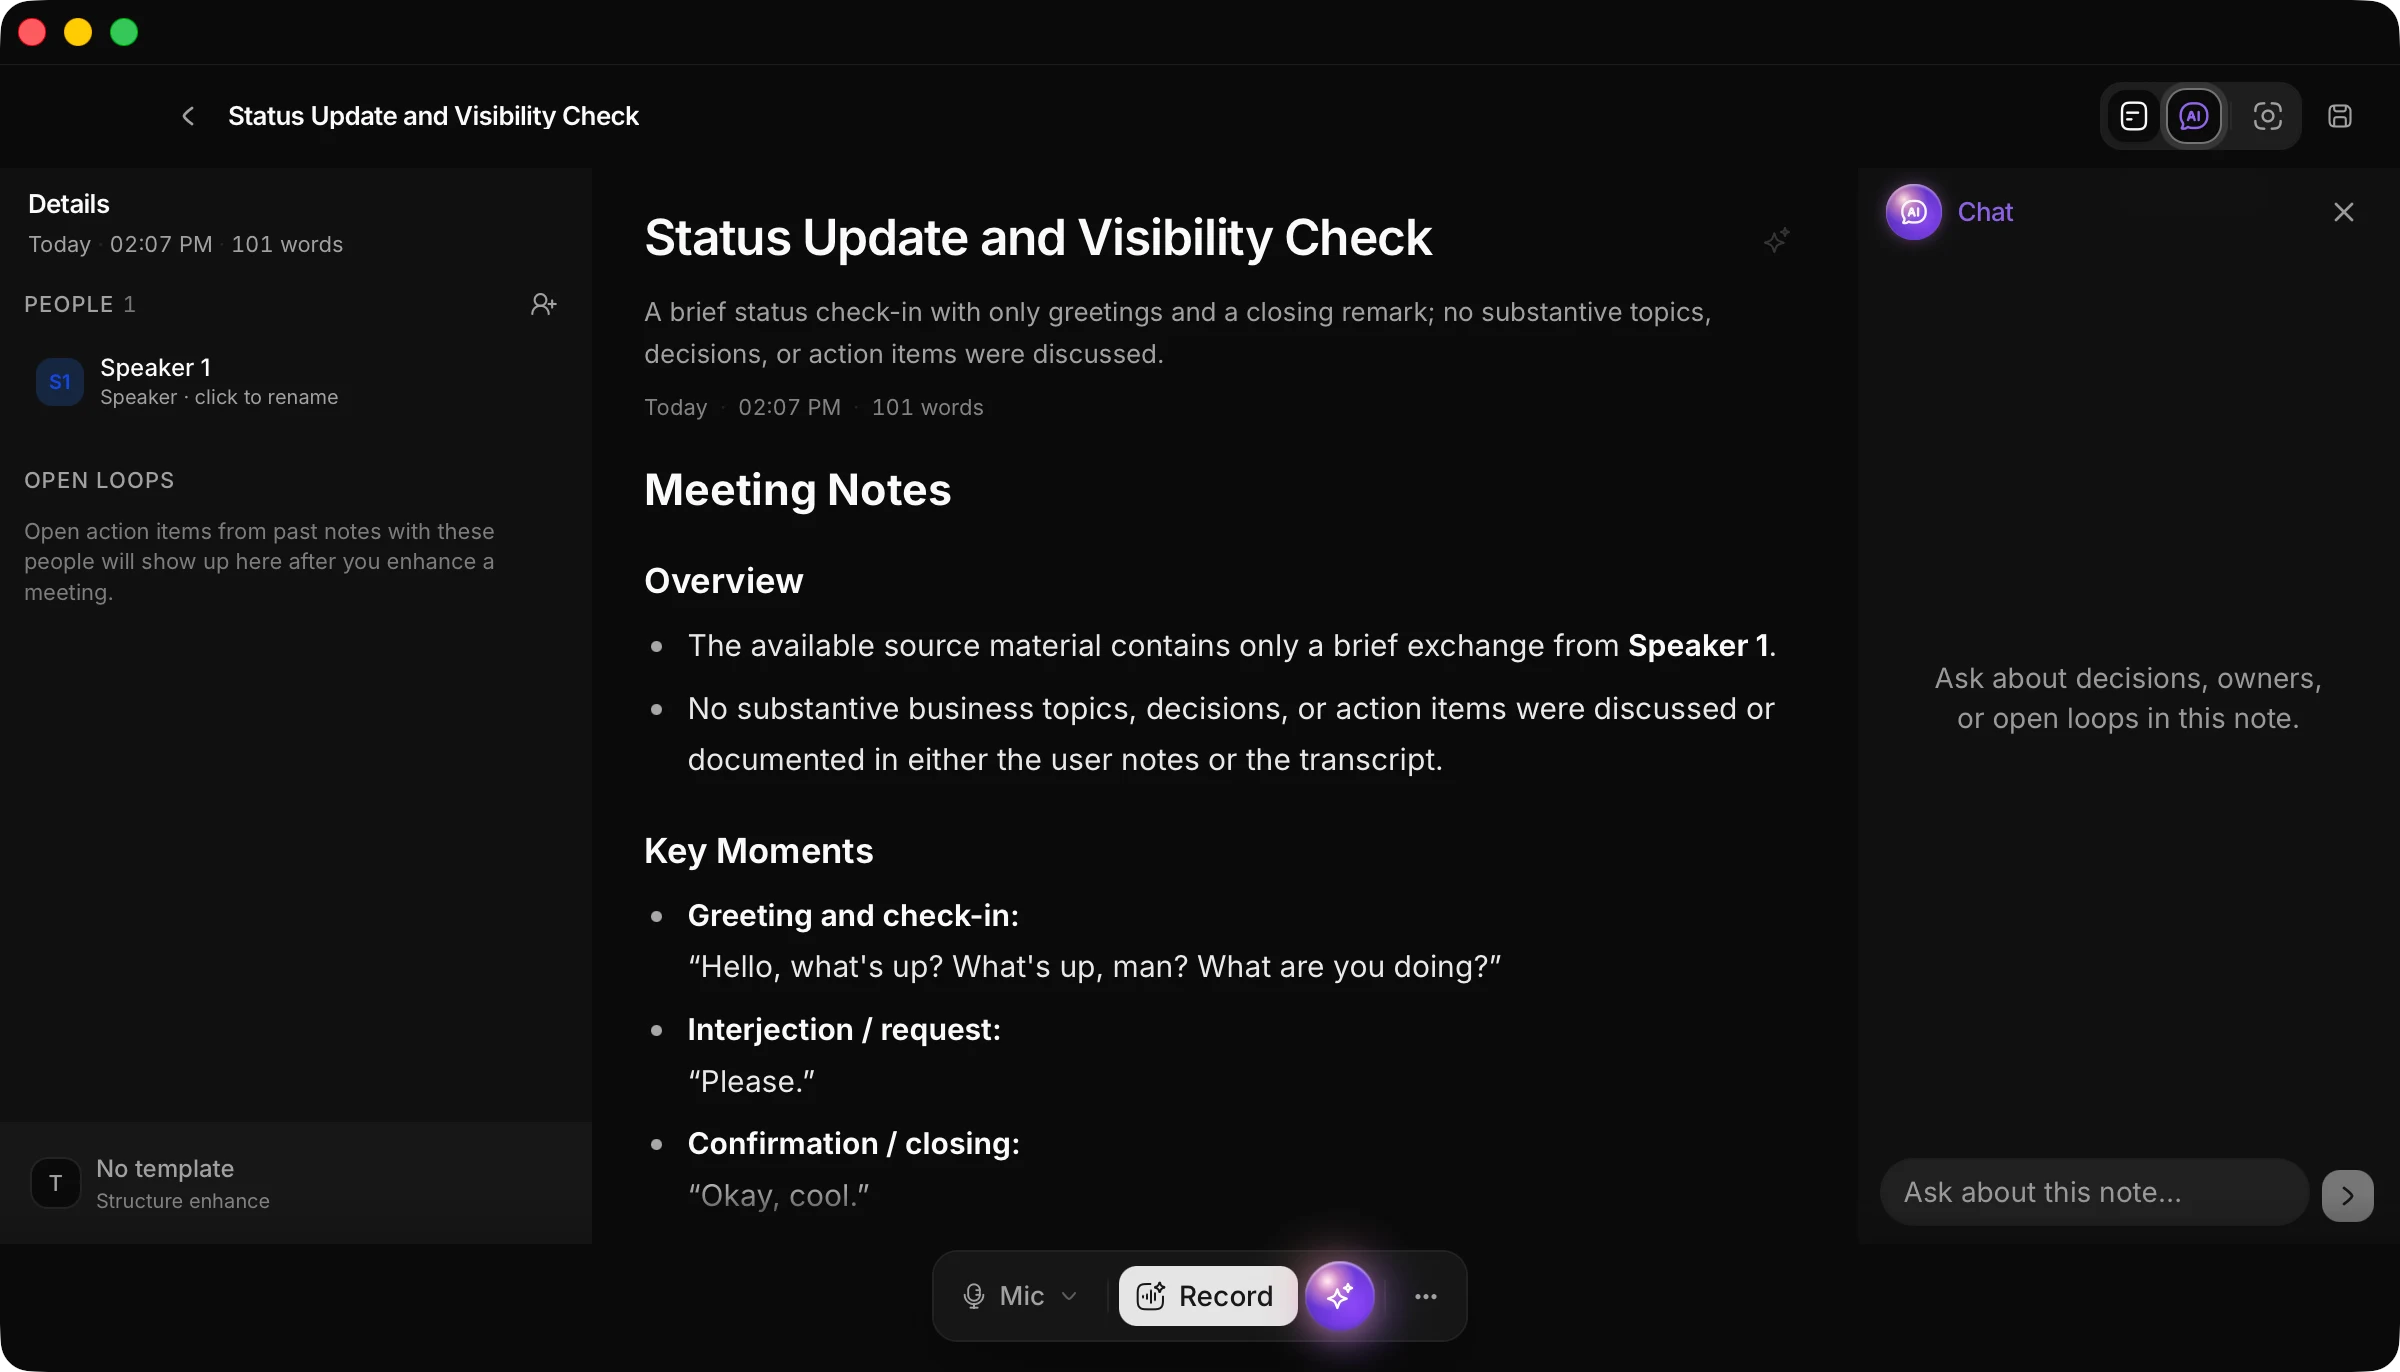***Optional follow-up***
## What it does
- Capture microphone audio, system audio, or both without a meeting bot.
- Transcribe locally on Apple silicon and write the live transcript into an editable note.
- Turn conversations into structured notes, action items, people, and tags when you choose.
## Good to know
- Audio capture and speech recognition run locally on the Mac.
- Version 0.1.0 supports Apple silicon Macs running macOS 14 or later.
[contact](https://criston.dev/cdn-cgi/l/email-protection#7a1915140e1b190e3a190813090e1514541e1f0c) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Before Meeting | Criston Mascarenhas
url: https://criston.dev/products/before-meeting
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
Before Meeting
# Before Meeting
macOS menu bar app
A macOS menu bar app that keeps your next meeting from sneaking up on you.
Before Meeting turns upcoming calendar events into an always-visible menu bar reminder so you can stay focused without losing track of time. It watches your next event, shows a live countdown, and plays a custom or system sound shortly before the meeting begins.
[Download App](https://github.com/crstnmac/BeforeMeeting/releases/download/v1.0/before-meeting.dmg)
EventKit · AVFoundation · AppKit · Menu Bar · Notifications
## What it does
- Menu bar countdown for your next calendar meeting.
- Automatic calendar monitoring so the next event stays in view.
- Audio reminder before meetings start.
- Custom sound selection support.
- macOS notification support.
- Native SwiftUI macOS experience.
## How it works
1. 01Allow calendar and notification access.
2. 02Let the app watch your next event in the background.
3. 03Hear the reminder before the meeting begins.
## Good to know
- Requires calendar permission to detect meetings.
- Best experience on macOS 13 or later.
## Questions
What does Before Meeting do?+
Before Meeting is a macOS menu bar app that shows a live countdown to your next calendar event, plays audio reminders before meetings start, and sends native macOS notifications.
Is Before Meeting free?+
Yes, Before Meeting is completely free to download and use.
What macOS version is required?+
Before Meeting requires macOS 13 (Ventura) or later for the best experience.
[contact](https://criston.dev/cdn-cgi/l/email-protection#e98a86879d888a9da98a9b809a9d8687c78d8c9f) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Experience | Criston Mascarenhas
url: https://criston.dev/experience
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
Experience
Experience
Role history, product ownership, platform work, and technical leadership — 7 roles across 5 organizations, currently Senior Software Engineer at BarrierBreak.
[Download résumé](https://criston.dev/criston-mascarenhas-resume.pdf) [Contact](https://criston.dev/cdn-cgi/l/email-protection#c0a3afaeb4a1a3b480a3b2a9b3b4afaeeea4a5b6)
## [BarrierBreak](https://www.barrierbreak.com/)
Senior Software Engineer +Nov 2023 — Present
Senior engineer building enterprise product and platform tooling across browser extensions, automation services, multi-tenant APIs, dashboards, and developer workflows. Promoted in March 2026 in recognition of technical leadership, product impact, and ownership across the platform.
**[A11yInspect](https://www.barrierbreak.com/a11yinspect/) — Browser Extension**
- Designed and built Chrome extension for real-time WCAG 2.x compliance testing in live web pages
- Implemented automated accessibility rules engine combining DOM analysis, ARIA validation, and visual checks
- Built in-page code highlighting system mapping accessibility violations to exact DOM nodes and source locations
- Developed visual testing utilities for heading structure analysis, tab order visualization, and color contrast validation
- Optimized scan algorithms to run efficiently on complex, production-scale web applications
**[A11yNow](https://www.barrierbreak.com/a11ynow/) — Automated Testing Platform**
- Built browser-driven accessibility automation engine using Playwright with DOM traversal and computed style analysis
- Designed extensible rule evaluation framework with versioned WCAG mappings for continuous standards updates
- Implemented data architecture for issues, pages, scans, and historical trend analysis in PostgreSQL
- Integrated hybrid automation workflow combining machine detection with human validation for accurate reporting
**Platform Engineering**
- Built backend services with Node.js, Express, and PostgreSQL (Drizzle ORM) supporting multi-tenant data and role-based access
- Implemented scheduled scans, authentication management (HTTP Auth, Cookie Auth, Scripted Login), and secure credential storage
- Built a secure user impersonation feature that helped reproduce and debug production issues faster without disrupting customer workflows
- Created data visualization dashboards with React for accessibility metrics and compliance trend reporting
- Mentored developers through code reviews and ensured clean architecture and maintainable codebases
React · TypeScript · Node.js · Express · PostgreSQL · Drizzle ORM · Playwright · Tailwind CSS · Chrome Extension · WCAG · ARIA · Redis · MongoDB
## [Timeless Ventures](https://timeless.co/)
Frontend Software Engineer +Oct 2022 — Oct 2023
- Developed and maintained reusable React Native and Next.js components for internal design system
- Executed proof-of-concept applications evaluating emerging technologies including React Query, Zustand, and Supabase
- Contributed composable components to open-source library [adaptui/react-native-tailwind](https://github.com/adaptui/react-native-tailwind)
- Collaborated with design team using Figma to implement responsive, production-ready interfaces
- Integrated Supabase backend with PostgreSQL for data synchronization and authentication
React Native · TypeScript · Next.js · React Query · Figma · Zustand · Supabase · PostgreSQL
## [GlobalLogic India](https://www.globallogic.com/)
Software Engineer +Jul 2022 — Sep 2022
- Led frontend migration of a medical supply chain management system from AngularJS to Angular 12
- Shipped inventory tracking, order management, and reporting modules on the new stack
- Added unit and integration tests to reduce production regressions during the migration
- Conducted code reviews and kept technical documentation current for the team
Angular · TypeScript · JavaScript · RxJS · REST APIs
Associate Software Engineer +Sep 2021 — Jul 2022
- Developed and maintained Angular components for a healthcare supply chain management application
- Implemented responsive UI features with Angular Material and SCSS across browsers
- Fixed production bugs and performance issues on high-traffic frontend paths
- Documented component libraries and internal APIs for handoff and onboarding
Angular · TypeScript · JavaScript · Angular Material · SCSS
Software Engineer Intern +Mar 2021 — Sep 2021
- Completed internship training in JavaScript, HTML, CSS, and Angular fundamentals
- Built interactive web components as part of training projects
- Contributed bug fixes and small enhancements to the production codebase
- Received a full-time offer as Associate Software Engineer on completion
JavaScript · HTML · CSS · Angular · Git
## Free Software Movement Karnataka
Open Source Contributor +Jan 2018 — 2020
- Contributed to open-source initiatives promoting free software adoption in educational institutions
- Participated in community workshops and events focused on web development and open-source technologies
- Collaborated with community members on documentation and project contributions
Open Source · Community Building · Web Development
Volunteer community work (2018–2020), overlapping the SlashRTC internship in mid-2019.
## SlashRTC
UI/UX Design Intern +Jul 2019 — Aug 2019
- Designed user interface mockups and wireframes for web applications
- Converted designs to responsive HTML/CSS
- Worked with engineers to keep designs feasible and implementation-ready
UI/UX Design · HTML · CSS · Wireframing
[contact](https://criston.dev/cdn-cgi/l/email-protection#e5868a8b91848691a586978c96918a8bcb818093) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Criston Mascarenhas | Senior Software Engineer
url: https://criston.dev/
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
Criston Mascarenhas
Senior Software Engineer
I figure out hard problems and turn them into products.
Currently at [BarrierBreak](https://www.barrierbreak.com/), based in Karnataka, India.
[contact](https://criston.dev/cdn-cgi/l/email-protection#21424e4f554042556142534852554e4f0f454457) [résumé](https://criston.dev/criston-mascarenhas-resume.pdf)
## Selected work
[all work](https://criston.dev/work)
[**A11yInspect**Real-time WCAG accessibility testing inside the browser, on live production pages.Chrome extension · BarrierBreak](https://chromewebstore.google.com/detail/a11yinspect-accessibility/giaolcgipopikbjonacmaokkeiaolmfp) [**A11yNow**Browser-driven automated accessibility engine with versioned WCAG rule mappings.Accessibility testing platform · BarrierBreak](https://www.barrierbreak.com/a11ynow/) [**SemPDF**Zero-dependency TypeScript library for generating, tagging, and editing accessible PDFs.TypeScript PDF library](https://sempdf.criston.dev/) [**Before Meeting**A macOS menu bar app that keeps your next meeting from sneaking up on you.macOS menu bar app](https://criston.dev/products/before-meeting) [**StackWatch**Privacy-first server monitoring and control for Linux boxes, straight from your Android phone.Android server monitoring app](https://criston.dev/products/stackwatch) [**Myna Notes**Live meeting transcription that stays on your Mac and inside an editable note.Private meeting notes · macOS](https://criston.dev/work/myna-notes)
## Writing
[all writing](https://criston.dev/writing)
- [A Safe Masked UAT Refresh Pipeline with Dokploy and GreenmaskJun 18, 2026](https://criston.dev/writing/safe-masked-uat-refresh-pipeline-dokploy-greenmask)
- [Building a Production-Grade Accessibility Scanning PlatformJun 16, 2026](https://criston.dev/writing/building-a-production-grade-accessibility-scanning-platform)
[contact](https://criston.dev/cdn-cgi/l/email-protection#e98a86879d888a9da98a9b809a9d8687c78d8c9f) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Why We Built Our Own Accessibility Engine (And What "Accuracy" Really Means) | Criston Mascarenhas
url: https://criston.dev/writing/why-we-built-our-own-accessibility-engine
description: Most accessibility scanners sort the world into violations and passes. We think that's the wrong model — and here's the thinking we built around instead.
---
Why We Built Our Own Accessibility Engine (And What "Accuracy" Really Means)
accessibility · WCAG · engineering
# Why We Built Our Own Accessibility Engine (And What "Accuracy" Really Means)
Most accessibility scanners sort the world into violations and passes. We think that's the wrong model — and here's the thinking we built around instead.
By [Criston Mascarenhas](https://criston.dev/about) · June 15, 2026 · 3 min read
Automated accessibility testing has a credibility problem. Run three popular scanners against the same page and you'll get three different issue counts — sometimes off by an order of magnitude. Teams learn to distrust the numbers, accessibility debt piles up, and the tools get blamed.
When we set out to build our scanning engine, we didn't start from "how do we find more issues?" We started from a harder question: how do we find the *right* issues, and how do we be honest about the ones a machine can't judge?
Here's the thinking behind it.
## [The problem with "violation or nothing"](#the-problem-with-violation-or-nothing)
Most scanners sort the world into two buckets: this is a violation, or it isn't. It's a comfortable model for a CI gate — red or green — but accessibility doesn't actually work that way.
A huge share of real accessibility barriers live in a grey zone that no static rule can resolve with confidence. Does this image's alt text actually describe the image, or is it just present? Is this heading meaningful, or filler? Does the reading order make sense? A binary engine has two bad options here: flag everything and drown the user in false positives, or stay silent and miss real problems.
We rejected the binary. Our engine returns a graded set of verdicts — issues that genuinely fail, issues that need a human to make the call, advisory suggestions, and confirmed passes. The "needs human review" category is the one we care most about, because it's where honest accessibility work actually happens. We surface those items by default instead of burying them where nobody looks.
## [Test the page a human would see, not the source](#test-the-page-a-human-would-see-not-the-source)
The second decision was about where testing happens. A lot of tooling reasons over static markup. But users don't experience your markup — they experience a rendered page: computed styles, applied fonts, actual layout, elements positioned off-screen, content revealed or hidden by CSS.
Our engine evaluates the fully rendered page in a real browser. That single choice eliminates whole classes of false positives and false negatives — particularly around visibility and colour contrast, where the answer depends entirely on what actually painted to the screen, not on what the HTML implied.
## [Generic rules find generic problems](#generic-rules-find-generic-problems)
The third decision was about granularity. A general-purpose rule like "interactive elements need an accessible name" is correct, but it's blunt. The right guidance for a missing name on an icon button is different from the guidance for a link wrapping an image, which is different again from an embedded frame or a custom widget.
We invested heavily in component-aware checks — logic that understands the specific context an element lives in and tailors both the verdict and the remediation advice accordingly. The payoff isn't just more findings; it's findings a developer can act on without first translating a generic complaint into their actual situation. Each issue carries who can fix it, which success criterion it maps to, and a concrete recommendation.
## [Accuracy is a discipline, not a feature](#accuracy-is-a-discipline-not-a-feature)
The uncomfortable truth is that an accessibility engine is never "done." Specifications evolve, the rules for computing an element's accessible name have real edge cases, and the gap between "technically present" and "actually usable" is where the hard engineering lives. We treat correctness as something we continuously measure and tighten, not a box we ticked at launch.
That's the whole philosophy: be precise where machines can be precise, be honest where they can't, and meet developers with advice they can use. Counting issues is easy. Counting the right ones — and admitting which ones still need human eyes — is the part worth building.
[contact](https://criston.dev/cdn-cgi/l/email-protection#d7b4b8b9a3b6b4a397b4a5bea4a3b8b9f9b3b2a1) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Building a Production-Grade Accessibility Scanning Platform | Criston Mascarenhas
url: https://criston.dev/writing/building-a-production-grade-accessibility-scanning-platform
description: An architectural deep-dive into A11yNow — the distributed web accessibility auditing backend I built at BarrierBreak. Browser pooling, distributed scheduling, multi-auth, error resilience, and a 600MB Docker image.
---
Building a Production-Grade Accessibility Scanning Platform
accessibility · architecture · TypeScript · infrastructure · engineering
# Building a Production-Grade Accessibility Scanning Platform
An architectural deep-dive into A11yNow — the distributed web accessibility auditing backend I built at BarrierBreak. Browser pooling, distributed scheduling, multi-auth, error resilience, and a 600MB Docker image.
By [Criston Mascarenhas](https://criston.dev/about) · June 16, 2026 · 13 min read
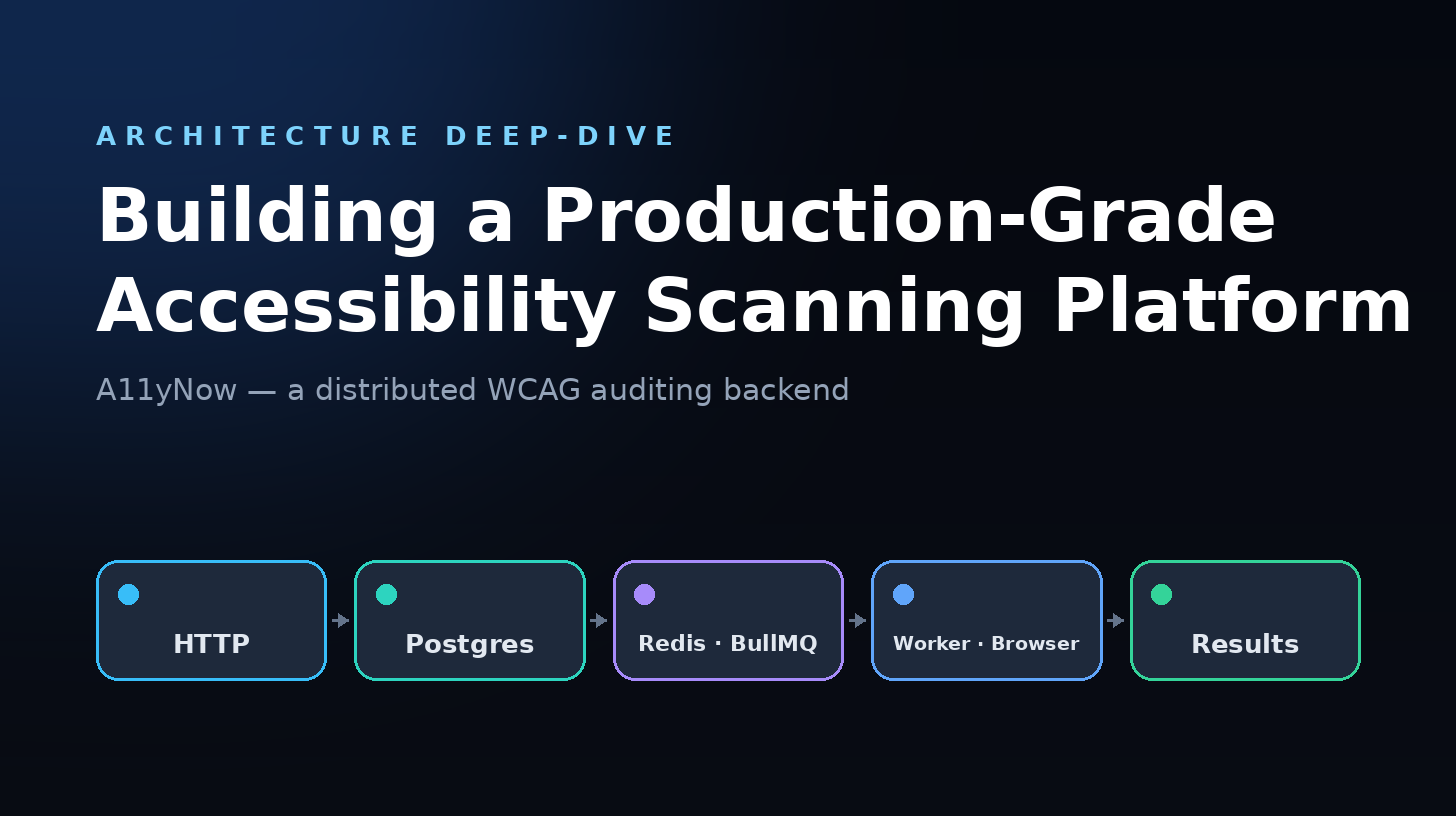
When your job is to scan thousands of web pages for WCAG 2.1 compliance across multiple browsers, device viewports, and authentication schemes — all while handling scheduled cron jobs, queued workloads, distributed locking, and screenshots — you quickly learn that the hard part isn't the accessibility rules. It's the infrastructure.
This post walks through the architecture of **A11yNow**, the backend I designed and built at BarrierBreak to automate accessibility auditing at scale. Every decision here was driven by real production pain: browser memory leaks, duplicate scheduled executions, OOM kills, and flaky auth sessions.
## [1. The scan pipeline (at 10,000 feet)](#1-the-scan-pipeline-at-10000-feet)
A scan request flows through five stages:
```
HTTP POST /scan → PostgreSQL (record) → Redis/BullMQ (queue) → Worker (browser + scan engine) → PostgreSQL (results)
```
Here's the exact call chain:
1. The controller validates input, checks usage quotas, and fetches project settings once (no N+1).
2. The core scanner service writes a scan-result row in PostgreSQL with status `pending`, then enqueues the job into BullMQ.
3. BullMQ stores the job in Redis with 3 retry attempts, exponential backoff, and bounded retention (1h completed / 24h failed).
4. The scan worker unpacks the job payload into a scan context and calls into the scanner service.
5. The scanner service runs the real work:
```
private async executeScan(context: ScanContext, persistence: IScanPersistence) {
// 1. Get or create a per-project browser manager (LRU-cached)
const browserManager = await this.getProjectBrowserManager(
context.projectId, context.browserType, context.devicePreset
);
const page = await browserManager.acquirePage();
// 2. Authenticate if needed (basic, bearer, cookie, NTLM, or multi-step UI)
if (authConfig) {
const result = await this.authHandler.authenticate(page, url, authConfig, sessionId);
page = result.page;
}
// 3. Navigate and execute the accessibility engine
await page.goto(url);
const result = await this.scanExecutor.execute(page, context, this.config);
// 4. Store issues with SHA-256 fingerprinting (deduplication)
const createdIssues = await storeIssues(result.issues, projectId, pageId, ...);
// 5. Capture screenshots of each issue (sequential — can't parallelise DOM highlights)
if (context.takeScreenshot) {
page = await this.processScreenshotsSequential(page, createdIssues, context);
}
// 6. Update status to COMPLETED only after all data is persisted
await persistence.updateStatus(context.scanId, ScanStatus.COMPLETED);
}
```
Important
The key insight: status is only set to `COMPLETED` after issues are stored **and** screenshots are uploaded to S3. There's no "partial success" state — the scan is either fully done or it's still in progress.
## [2. Browser pooling with LRU + page queues](#2-browser-pooling-with-lru--page-queues)
You can't launch a new Chromium instance for every scan. A single browser process eats \~300MB+. With dozens of concurrent scans, you'd OOM in minutes. My solution: per-project browser pooling with LRU eviction and a page request queue.
### [LRU cache of browser managers](#lru-cache-of-browser-managers)
Each project gets its own browser manager instance, cached by `projectId:browserType:devicePreset`:
```
this.projectBrowserManagers = new LRUCache({
max: 12, // Max 12 concurrent browser instances
ttl: 1000 * 60 * 10, // 10-minute TTL
ttlAutopurge: true, // Auto-evict stale browsers
updateAgeOnGet: true, // Reset TTL on access (prevent mid-scan eviction)
dispose: (value, key) => {
// Async shutdown tracked via pendingDisposals set
const p = value.shutdown().finally(() => this.pendingDisposals.delete(p));
this.pendingDisposals.add(p);
},
});
```
When the LRU reaches `max`, the least-recently-used browser is evicted and gracefully shut down. The `dispose` handler tracks shutdown promises so the graceful-shutdown handler can await them.
### [Page request queue (not just another pool)](#page-request-queue-not-just-another-pool)
Each browser manager maintains a configurable pool of Playwright `Page` objects (default 5). When the pool is full, requests are queued rather than throwing:
```
async acquirePage(): Promise {
if (this.activePagesSet.size < this.maxPoolSize) {
const browser = await this.getBrowser();
const pageContext = await browser.newContext(contextOptions);
const page = await pageContext.newPage();
this.activePagesSet.add(page);
return page;
}
// Pool full — queue the request with a 120s timeout
return new Promise((resolve, reject) => {
const timeout = setTimeout(() => {
this.pageRequestQueue.splice(/* remove this request */);
reject(new Error('Timed out waiting for available page'));
}, this.maxQueueWaitTimeMs);
this.pageRequestQueue.push({ resolve, reject, timestamp: Date.now(), timeout });
});
}
```
When a page is released, the queue is processed immediately (not just on a timer). This gives sub-5ms response when capacity is available, but can backpressure up to 20 queued requests before logging warnings.
### [Why not a generic connection pool?](#why-not-a-generic-connection-pool)
Generic pools (like `generic-pool`) work for database connections. Browser pages are different:
- Each page needs its own browser context (isolated cookies, localStorage).
- Ad blocking is enabled per-page via a shared `PlaywrightBlocker` engine (30MB, cached at module level to avoid N× duplication).
- Page-close events auto-close their context for clean teardown.
- Context options are browser-type aware (Firefox skips mobile emulation, Linux WebKit skips touch).
## [3. The scheduling system: distributed locks done right](#3-the-scheduling-system-distributed-locks-done-right)
Scheduled scans were the hardest production bug to fix. The original implementation had race conditions: two instances or two cron ticks would both pick up the same "due" schedule and queue duplicate jobs. The fix was three-pronged.
### [3a. Distributed locking via Redis SET NX](#3a-distributed-locking-via-redis-set-nx)
```
async acquire(options: LockOptions = {}): Promise {
for (let attempt = 0; attempt <= retries; attempt++) {
const result = await redis.set(
`lock:${this.lockKey}`,
this.lockValue,
'PX', ttl, // Millisecond expiry
'NX' // Only set if not exists
);
if (result === 'OK') { this.acquired = true; return true; }
await this.sleep(retryDelay);
}
return false;
}
async release(): Promise {
// Lua script: atomic compare-and-delete (only the lock owner can release)
const script = `
if redis.call("get", KEYS[1]) == ARGV[1] then
return redis.call("del", KEYS[1])
else return 0 end
`;
const result = await redis.eval(script, 1, this.lockKey, this.lockValue);
// ...
}
```
Lock acquisition uses `SET NX PX` — Redis's native atomic "set if not exists with expiry." The release uses a Lua script for atomic compare-and-delete, preventing a stale client from releasing someone else's lock.
### [3b. Idempotent job IDs](#3b-idempotent-job-ids)
Each scheduled execution gets a deterministic job ID:
```
const jobId = ScheduleCalculator.generateJobId(schedule.id, now);
// e.g. "schedule-abc123-2026-06-16"
const existingExecution = await prisma.scheduleExecution.findUnique({
where: { jobId }
});
if (existingExecution) {
logger.info('Schedule already executed today, skipping');
return;
}
```
Even if the lock fails, the database enforces idempotency: the execution record has a unique constraint on `jobId`.
### [3c. Atomic nextRunAt update (before queuing)](#3c-atomic-nextrunat-update-before-queuing)
Warning
The critical race: update `nextRunAt` **then** queue scans. If the update happens after queuing and the process crashes, the schedule appears "due" again on the next tick.
```
// Transaction: atomically update schedule + create execution record
const execution = await prisma.$transaction(async (tx) => {
await tx.scanSchedule.update({
where: { id: schedule.id },
data: { lastRunAt: now, nextRunAt }
});
return await tx.scheduleExecution.create({
data: { scheduleId: schedule.id, status: 'PENDING', jobId, ... }
});
});
// Only NOW queue the actual scans
for (const page of schedule.project.pages) {
await this.scanQueue.addScan({ ... });
}
```
`nextRunAt` is advanced before anything is queued, inside the same database transaction as the execution record. If the process dies mid-queue, the next tick sees a future `nextRunAt` and skips it.
### [3d. First-run skip](#3d-first-run-skip)
On startup, the cron fires immediately (within 1 minute). Without protection, every deployment would queue every due schedule:
```
if (this.isFirstRun) {
logger.info('First run - skipping all schedules');
this.isFirstRun = false;
return;
}
```
## [4. Multi-auth: five authentication strategies](#4-multi-auth-five-authentication-strategies)
Authenticated pages are common in enterprise a11y testing — internal dashboards, staging environments, client portals. The authentication handler supports five strategies:
| Type | Mechanism | Validation |
| --- | --- | --- |
| basic | HTTP Basic Auth header | username + password required |
| bearer | `Authorization: Bearer` header | token required |
| cookie | Set named cookies | array of `{name, value}` objects |
| ntlm | Windows Integrated Auth | username + password (CNTLM proxy) |
| ui | Multi-step form login | `usernameSelector` + `passwordSelector`, or a `steps[]` array |
Sessions are persisted to Redis with a TTL. On the next scan, the saved session is restored — no need to re-login:
```
if (sessionId) {
const hasSavedSession = await authService.hasAuthSession(sessionId);
if (hasSavedSession) {
const restored = await authService.restoreAuthSession(page, sessionId);
if (restored.success) return { success: true, page: restored.page };
// Session stale — delete and fall through to fresh login
await authService.deleteAuthSession(sessionId);
}
}
// Fresh authentication
await page.goto('about:blank'); // Clean slate
const authResult = await authService.authenticate(page, url, authConfig);
if (authResult.success && sessionId) {
await authService.saveAuthSession(authResult.page, sessionId);
}
```
## [5. Error resilience: discriminated errors + retry with jitter](#5-error-resilience-discriminated-errors--retry-with-jitter)
Errors in browser automation are messy: a page load might fail because of a network hiccup (retryable), or because the URL is a 404 (not retryable). The system uses discriminated scan errors:
```
type ErrorCode =
| 'BROWSER_LAUNCH_FAILED'
| 'PAGE_LOAD_FAILED'
| 'AUTH_FAILED'
| 'SCAN_TIMEOUT'
| 'SCAN_CANCELLED'
| 'ADBLOCKER_INIT_FAILED'
| 'UNKNOWN_ERROR';
interface ScanError {
code: ErrorCode;
message: string;
retryable: boolean;
}
```
The retry handler wraps scan execution with exponential backoff + 30% jitter:
```
const result = await this.retryHandler.execute(
async () => this.executeScan(context, persistence),
`scan-${context.scanId}`,
{
maxRetries: 3,
retryableErrors: [
ErrorCode.BROWSER_LAUNCH_FAILED,
ErrorCode.PAGE_LOAD_FAILED,
ErrorCode.SCAN_TIMEOUT
]
}
);
```
- `BROWSER_LAUNCH_FAILED` is retryable — browser processes crash, CDP endpoints drop.
- `AUTH_FAILED` is **not** retryable — wrong credentials won't fix themselves.
- Local browser launch has its own retry loop (2 retries), falling back to `--headless=new` on the final attempt.
## [6. Multi-browser + remote Browserless](#6-multi-browser--remote-browserless)
The scanner supports Chromium, Firefox, and WebKit via Playwright. Browser selection is environment-driven:
```
BROWSER_PROVIDER=auto # prefers remote Browserless, falls back to local
BROWSER_PROVIDER=local # always launches locally
BROWSER_PROVIDER=browserless # always connects to remote CDP
```
Remote mode connects to Browserless via `connectOverCDP()`:
```
if (shouldUseRemoteBrowser() && browserlessEndpoint) {
// CDP first (Browserless native), Playwright protocol fallback
try {
const browser = await playwrightChromium.connectOverCDP(wsEndpoint, { timeout: 30000 });
return browser;
} catch (cdpError) {
if (errorMessage.includes('Protocol error')) {
// Not Browserless — try standard Playwright connect
return await playwrightChromium.connect(wsEndpoint, { timeout: 30000 });
}
throw cdpError;
}
}
```
Local Chromium uses `playwright-extra` with the stealth plugin to evade bot detection — critical for scanning sites that block headless browsers. Context options are browser-aware:
```
private buildContextOptions() {
const opts = { viewport, deviceScaleFactor, javaScriptEnabled: true, ignoreHTTPSErrors: true };
if (this.browserType === 'firefox') {
// Skip isMobile — Firefox doesn't support it
} else if (this.browserType === 'webkit' && process.platform === 'linux') {
// Skip hasTouch — Linux WebKit doesn't support it
} else {
opts.isMobile = this.config.isMobile;
}
return opts;
}
```
## [7. The data model: issue fingerprinting for deduplication](#7-the-data-model-issue-fingerprinting-for-deduplication)
With 35+ Prisma models, the schema is comprehensive. The core innovation is issue fingerprinting:
```
model Issue {
id String @id @default(cuid())
fingerprint String? // SHA-256 hash of code + selector + context
code String // rule code (e.g. "BB10447")
selector String // CSS selector of offending element
context String? // Surrounding HTML snippet
severity String // Critical | Major | Minor
successCriteria String? // WCAG SC reference (e.g. "1.1.1")
screenshotKey String? // S3 key
screenshotUrl String? // Presigned URL
assignee Int[] @default([])
reviewStatus String @default("open")
activities Json[] @default([])
occurrences IssueOccurrence[] // Which scans found this issue
project Project @relation(...)
page Page @relation(...)
}
```
The fingerprint is a SHA-256 of code + selector + context. When the same `![]() ` without alt text appears in scan #47, it's recognized as the same issue from scan #1 — no duplicate row, just a new `IssueOccurrence` record.
The scan-result model carries a `batchId` for grouping related scans, `browserType` and `devicePreset` for environment tracking, and a computed `batchStatus` for efficient querying.
## [8. The Docker build: 5 stages to 600MB](#8-the-docker-build-5-stages-to-600mb)
A Node.js app with Playwright, Prisma, adblocker engines, and three workspace packages is heavy. The monolithic `node_modules` alone can exceed 1GB. The Dockerfile uses five stages to strip it to \~600MB:
```
Stage 1 (base): Node 22 Alpine + build tools (python3, make, g++)
Stage 2 (dependencies): Install ALL deps, skip Playwright browser downloads
Stage 3 (builder): Compile TypeScript, build workspace packages, generate Prisma client
Stage 4 (prod-deps): yarn workspaces focus --production, then aggressively clean
Stage 5 (production): Node 22 Alpine runtime, non-root user, no browser binaries
```
The aggressive cleaning in stage 4 is worth looking at:
```
RUN yarn workspaces focus --production && \
find node_modules -name "*.md" -delete && \
find node_modules -name "*.ts" ! -name "*.d.ts" -delete && \
find node_modules -name "*.map" -delete && \
find node_modules -type d -name "test" -exec rm -rf {} + && \
find node_modules -type d -name "tests" -exec rm -rf {} + && \
find node_modules -type d -name "docs" -exec rm -rf {} + && \
find node_modules -type d -name "examples" -exec rm -rf {} +
```
TypeScript source, source maps, tests, docs, examples, benchmarks, changelogs — all stripped. The final image:
- Runs as a non-root `nodejs` user (UID 1001).
- Has a health-check endpoint ( `curl /health`).
- Uses `NODE_OPTIONS="--max-old-space-size=4096"` for memory headroom.
- Binds to `0.0.0.0` on the configured port.
- Removes Playwright browser binaries (uses remote Browserless).
## [9. Graceful shutdown](#9-graceful-shutdown)
Production deploys aren't polite. SIGTERM arrives with a deadline. The shutdown handler runs a five-step sequence:
```
const gracefulShutdown = async (signal: string) => {
// 1. Stop polling services (JIRA, GitHub)
jiraPollingService.stop();
githubPollingService.stop();
// 2. Stop JIRA sync worker
await workerServices.jiraSyncWorker.stop();
// 3. Stop the scheduler (prevents new cron triggers)
workerServices.schedulerService.stop();
// 4. Close HTTP server (stop accepting new requests)
await new Promise(resolve => server.close(resolve));
// 5. Wait 5s for active jobs to finish
await new Promise(resolve => setTimeout(resolve, 5000));
process.exit(0);
};
process.on('SIGTERM', () => gracefulShutdown('SIGTERM'));
process.on('SIGINT', () => gracefulShutdown('SIGINT'));
```
Note
The 5-second grace period gives BullMQ workers time to mark their current job as completed or failed before Redis loses the lock. In-flight browser shutdowns from LRU eviction can also be awaited before exit.
## [10. What I'd do differently](#10-what-id-do-differently)
1. **Structured concurrency.** The active-scan and pending-disposal sets work but are fragile. A proper structured-concurrency primitive (like Effect, or explicit `Promise.race` with cleanup) would be safer.
2. **Browser manager as a standalone service.** Right now, browser managers live inside the scanner service's LRU. A separate browser-pool service with its own lifecycle would be cleaner — the scanner shouldn't own browser state.
3. **More aggressive TypeScript strictness.** `strict: false` was pragmatic for velocity, but it's hiding bugs. Gradual adoption of `strictNullChecks` would catch null-pointer issues that currently surface as runtime errors.
4. **Observability.** Structured logging (Pino) is there, but there are no OpenTelemetry traces. A scan that takes 30 seconds should be traceable through queue → worker → browser → engine → DB — right now you grep logs.
5. **Worker autoscaling.** Worker concurrency is static (default 5). Real scan workloads spike — a KEDA or custom autoscaler based on queue depth would handle bursts better than a fixed pool.
## [Key takeaways](#key-takeaways)
- **LRU-cached browser pooling beats launching per-scan.** \~300MB per browser process adds up fast.
- **Distributed locks need three layers:** Redis `SET NX` (speed), idempotent job IDs (correctness), and atomic `nextRunAt` updates (race prevention).
- **Update state before side effects.** Advancing `nextRunAt` in a transaction *before* queuing scans prevents duplicate execution on crash.
- **Docker image size matters for CI/CD velocity.** Stripping TypeScript, docs, and tests from `node_modules` cut the image by \~40%.
- **Error discrimination enables smart retries.** Not all failures should be retried — bad auth shouldn't, but a CDP disconnect should.
[contact](https://criston.dev/cdn-cgi/l/email-protection#bcdfd3d2c8dddfc8fcdfced5cfc8d3d292d8d9ca) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: StackWatch | Criston Mascarenhas
url: https://criston.dev/products/stackwatch
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
StackWatch
# StackWatch
Android server monitoring app
Privacy-first server monitoring and control for Linux boxes, straight from your Android phone.
StackWatch lets you monitor and manage Linux servers directly from Android over SSH. Track live CPU, RAM, disk, and container health, keep a rolling 30-day metric history, receive threshold alerts, and jump into logs, commands, files, or a full terminal session when something needs attention.
[Get it on Google Play](https://play.google.com/store/apps/details?id=com.crstnmac.stackwatch)
SSH · Docker · Widgets · SFTP · Terminal
## Inside the product
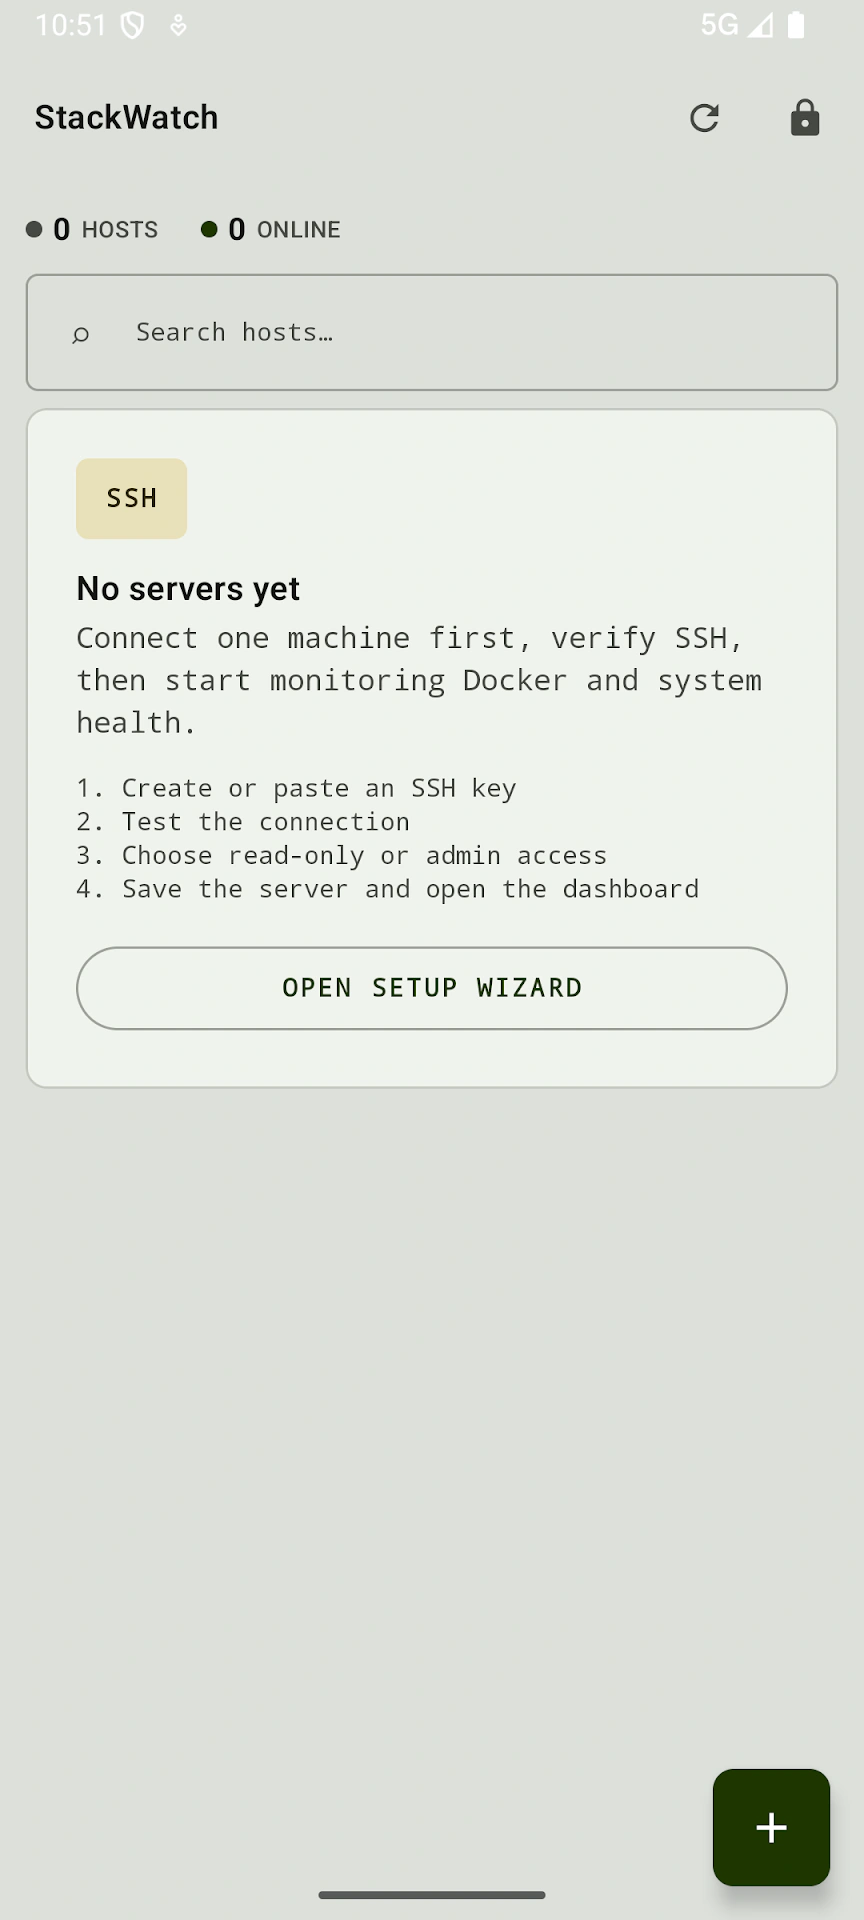***Fleet overview**Keep host status one glance away with a mobile dashboard and home screen widgets.*
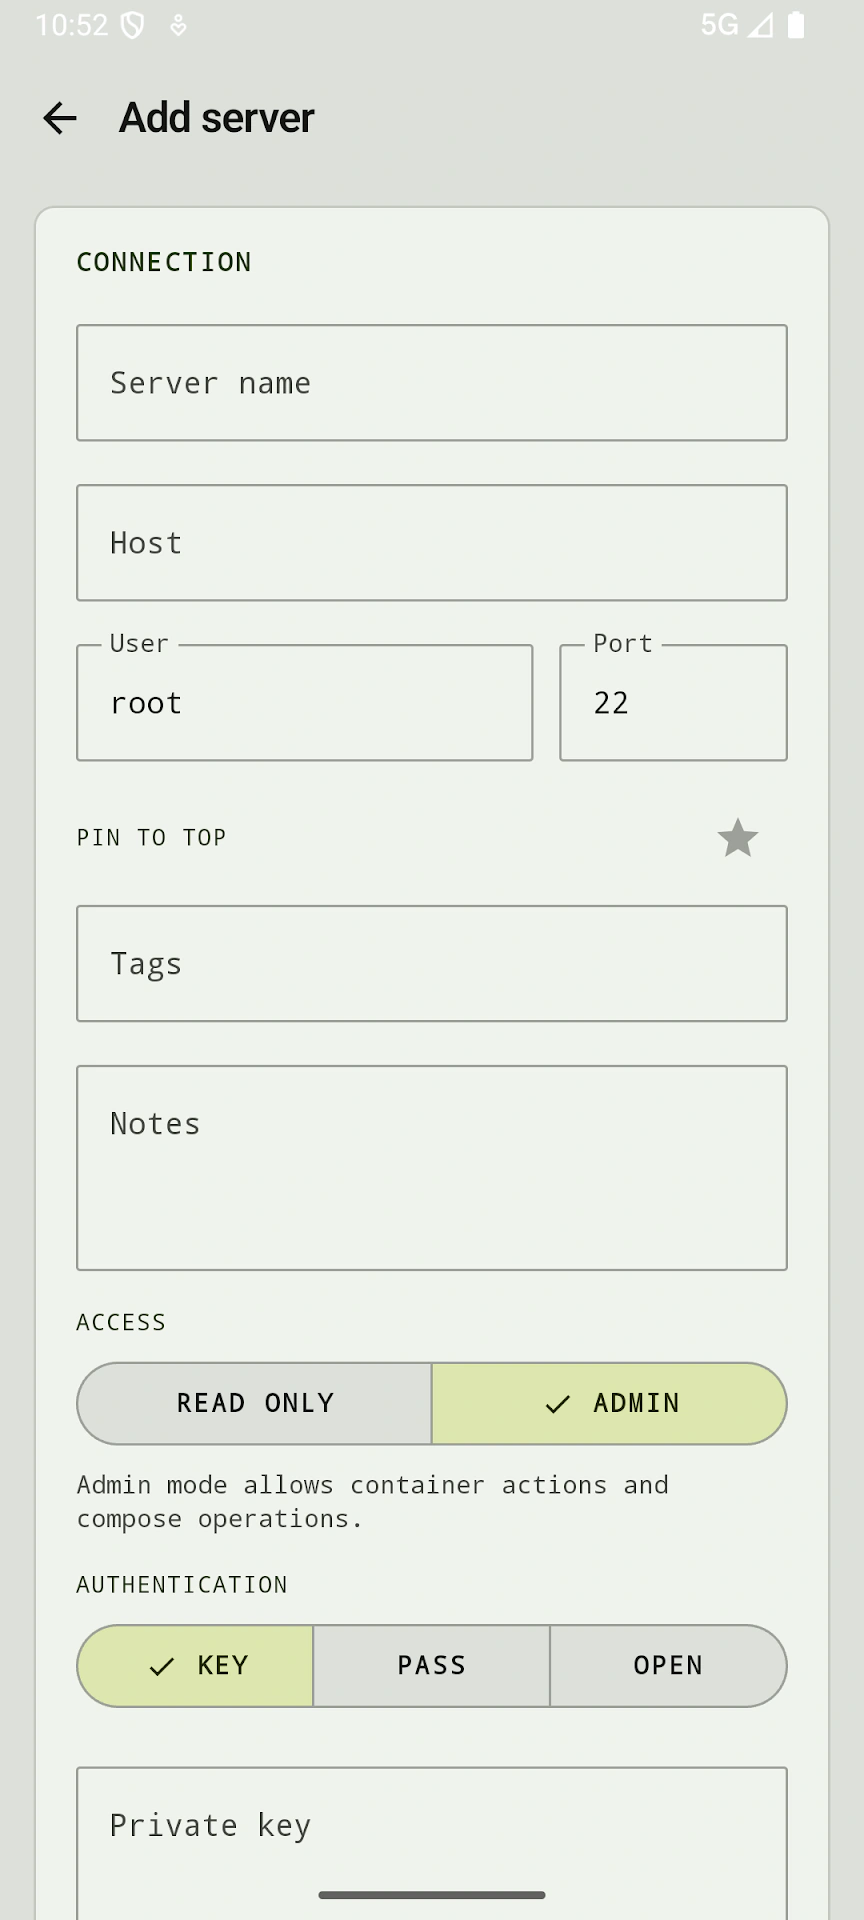***Fast server setup**Add hosts with SSH details, labels, notes, and authentication options directly from your phone.*
## What it does
- Live CPU, RAM, disk, and container metrics for Linux servers you connect to over SSH.
- Docker container controls with start, stop, restart, pull, recreate, Compose grouping, and live logs.
- Rolling 30-day metric history with CSV export so you can spot trends or investigate incidents.
- Threshold-based push alerts for CPU, RAM, and disk so critical changes do not quietly slide by.
- HTTP and TCP service monitors for web apps, APIs, and databases alongside host metrics.
- Remote command center, SFTP file browser, quick text edits, and a full mobile SSH terminal in one app.
## How it works
1. 01Add a Linux server with its host, port, and SSH credentials.
2. 02StackWatch connects directly from your Android device and starts streaming live system and container health.
3. 03Use widgets, alerts, logs, files, commands, or the built-in terminal whenever your infrastructure needs attention.
## Good to know
- No cloud account or third-party relay is required. Connections go directly from your device to your servers over SSH.
- Credentials stay on-device in Android's encrypted storage, and you can add an optional biometric lock for extra protection.
- Best fit for developers, sysadmins, and homelab setups where SSH access is already available through your network or VPN.
## Questions
Does StackWatch require a cloud account?+
No. StackWatch connects directly to your Linux servers over SSH, so there is no cloud account or third-party relay required.
What can I manage from the app?+
You can monitor live system metrics, review container health, manage Docker actions, inspect logs, run commands, browse files over SFTP, define service checks, and open a full SSH terminal session.
Does server data leave my network?+
StackWatch is designed so connections stay end-to-end encrypted over SSH and credentials remain stored on-device using Android's encrypted storage.
[contact](https://criston.dev/cdn-cgi/l/email-protection#b0d3dfdec4d1d3c4f0d3c2d9c3c4dfde9ed4d5c6) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: A Safe Masked UAT Refresh Pipeline with Dokploy and Greenmask | Criston Mascarenhas
url: https://criston.dev/writing/safe-masked-uat-refresh-pipeline-dokploy-greenmask
description: How I set up a repeatable PostgreSQL UAT refresh flow that reads production, masks sensitive data with Greenmask, and restores only into a disposable UAT database.
---
A Safe Masked UAT Refresh Pipeline with Dokploy and Greenmask
PostgreSQL · Dokploy · Greenmask · infrastructure · security
# A Safe Masked UAT Refresh Pipeline with Dokploy and Greenmask
How I set up a repeatable PostgreSQL UAT refresh flow that reads production, masks sensitive data with Greenmask, and restores only into a disposable UAT database.
By [Criston Mascarenhas](https://criston.dev/about) · June 18, 2026 · 12 min read
UAT is useful only when it behaves enough like production to catch real problems. The awkward part is that production-like data is exactly the thing you should not casually copy into another environment.
I wanted a refresh flow with a very boring contract:
```
Production Postgres -> masked dump -> UAT Postgres
```
Production is the source. UAT is the target. Production should never be restored into, dropped, modified, or masked in place.
This post is the setup I use with Dokploy, PostgreSQL, and Greenmask. It is intentionally practical. The main goal is not clever masking. The main goal is a repeatable pipeline where the dangerous parts are obvious, isolated, and hard to point at the wrong database.
## [The Mental Model](#the-mental-model)
The whole pipeline has three moving pieces:
| Piece | Role | What Greenmask does |
| --- | --- | --- |
| Production database | Live application data | Reads from it during `dump` |
| Greenmask runner | Transformation boundary | Creates the masked dump |
| UAT database | Disposable test copy | Receives data during `restore` |
The rule I keep coming back to is this:
```
dump.pg_dump_options.dbname -> production
restore.pg_restore_options.dbname -> UAT
```
Important
That one distinction matters more than any individual masking rule. The dump side can read production. The restore side is destructive and must only point at UAT.
## [Create a Real UAT Database](#create-a-real-uat-database)
Start with a separate PostgreSQL service in Dokploy. Not a different schema in the same database. Not a reused database with a different application URL. A separate service with separate credentials.
For example:
```
Production DB service: app-prod-postgres
UAT DB service: app-uat-postgres
```
A good baseline looks like this:
```
Production:
Host: app-prod-postgres
Database: app_prod
User: prod_readonly_user
Permission: SELECT/read-only
UAT:
Host: app-uat-postgres
Database: app_uat
User: uat_restore_user
Permission: owner or restore-capable
```
The production user should be read-only if your schema allows it. Greenmask does not need to insert, update, delete, truncate, drop, alter, or create anything in production during the dump. That permission boundary is the first real safety rail.
If someone later runs the wrong command, the production credentials should still be too weak to destroy anything.
## [Add a Greenmask Runner Container](#add-a-greenmask-runner-container)
Dokploy scheduled jobs run commands inside an existing container, so I keep a small Greenmask runner alive and target that container for manual and scheduled refreshes.
Here is the service:
```
services:
greenmask-runner:
image: greenmask/greenmask:latest
container_name: app-greenmask-runner
restart: unless-stopped
user: "0:0"
env_file:
- .env
volumes:
- ./greenmask-uat.yml:/config/greenmask.yml:ro
- greenmask-dumps:/dumps
entrypoint: ["/bin/sh", "-c"]
command: ["mkdir -p /tmp/greenmask /dumps && sleep infinity"]
volumes:
greenmask-dumps:
```
There are a few small things in there that save a lot of time.
The container runs `sleep infinity` because Dokploy needs a stable running container to execute scheduled jobs in. The command also creates `/tmp/greenmask` and `/dumps`, which avoids failures like this during `pg_dump`:
```
pg_dump: error: could not create directory "/tmp/greenmask/": No such file or directory
```
The `entrypoint` override is there because the Greenmask image starts with the `greenmask` binary by default. Without the override, Docker can treat `sh` as a Greenmask subcommand:
```
unknown command "sh" for "greenmask"
```
I use `user: "0:0"` for the first version because Dokploy volume ownership can otherwise block writes to `/dumps`:
```
mkdir /dumps/: permission denied
```
For a stricter setup, create the dump directory on the host and assign it to the UID/GID used by the Greenmask image. For the first pipeline test, I prefer getting the isolated utility container working first, then tightening filesystem permissions once the flow is proven.
## [Wire Greenmask in One Direction](#wire-greenmask-in-one-direction)
Put the Greenmask config beside your Compose file. I usually call it:
```
greenmask-uat.yml
```
The important sections are `storage`, `dump`, `restore`, and `transformation`.
```
storage:
type: "directory"
directory:
path: "/dumps"
dump:
pg_dump_options:
# Production source database.
# Greenmask reads from this database during dump.
dbname: "postgresql://prod_user:${PROD_DB_PASSWORD}@app-prod-postgres:5432/app_prod"
no-owner: true
no-acl: true
restore:
pg_restore_options:
# UAT target database.
# Greenmask restores into this database.
dbname: "postgresql://uat_user:${UAT_DB_PASSWORD}@app-uat-postgres:5432/app_uat"
clean: true
if-exists: true
no-owner: true
no-acl: true
```
If both databases are on the same Compose network, the service names work as hosts.
Warning
The dangerous line is not hidden. It is `restore.pg_restore_options.dbname`. With `clean: true`, restore can drop existing objects in the target database before recreating them from the dump. That is exactly what you want for a clean UAT refresh, and exactly what you do not want anywhere near production.
`no-owner` and `no-acl` are also worth keeping. They stop production ownership and grant metadata from being replayed in UAT. Without them, restores often fail on role mismatches:
```
ERROR: role "prod_readonly_user" does not exist
Command was: GRANT SELECT ON TABLE public.users TO prod_readonly_user;
```
Do not create production roles in UAT just to satisfy restore metadata. Skip that metadata.
## [Decide What Gets Masked, Skipped, or Copied](#decide-what-gets-masked-skipped-or-copied)
Greenmask reads the table list from production during `dump`. Your config does not need to describe every table. It needs to describe the tables and columns that should be transformed, excluded, or handled carefully.
Most schemas fall into three buckets:
1. Mask sensitive columns.
2. Skip rows that should never enter UAT.
3. Copy safe lookup tables as-is.
The trick is to preserve the relational shape of production while replacing the sensitive values. Primary keys and foreign keys usually stay unchanged.
For example:
```
Production user id 42 -> UAT user id 42 -> [email protected]
Production project id 80 -> UAT project id 80 -> UAT Project 80
```
That gives you realistic joins, permissions, activity, reports, and edge cases without leaking the real customer details.
## [Mask the Obvious PII First](#mask-the-obvious-pii-first)
Start with users. Email, passwords, names, API keys, and any profile fields should be treated as sensitive.
```
transformation:
- schema: "public"
name: "users"
transformers:
- name: "Template"
params:
column: "email"
template: 'uat-user-{{- .GetColumnValue "id" -}}@example.test'
validate: true
- name: "Replace"
resolve_env: true
params:
column: "password"
value: "${UAT_PASSWORD_HASH?UAT_PASSWORD_HASH is required}"
validate: true
- name: "SetNull"
params:
column: "api_key"
```
This keeps each user stable across refreshes:
```
Production:
id: 42
email: [email protected]
UAT:
id: 42
email: [email protected]
```
The password field should be a real hash generated by your application, not something guessed by hand. Use the same password-hashing code path your app uses for normal users.
In Dokploy, the runner needs the values Greenmask resolves:
```
PROD_DB_PASSWORD=...
UAT_DB_PASSWORD=...
UAT_PASSWORD_HASH=...
GREENMASK_GLOBAL_SALT=...
```
Tip
Keep the global salt stable if you want deterministic masking across runs.
## [Rewrite URLs and Customer Entities](#rewrite-urls-and-customer-entities)
Production URLs can leak more than people expect: customer domains, private paths, signed assets, staging links, internal tools. I usually rewrite them rather than trying to preserve anything recognizable.
```
- schema: "public"
name: "urls"
transformers:
- name: "Template"
params:
column: "url"
template: 'https://uat-target.example.test/project-{{- .GetColumnValue "project_id" -}}/url-{{- .GetColumnValue "id" -}}'
validate: true
```
Example result:
```
Production:
id: 500
project_id: 80
url: https://customer-production-site.com/private/page
UAT:
id: 500
project_id: 80
url: https://uat-target.example.test/project-80/url-500
```
The same applies to customer-facing entities:
```
- schema: "public"
name: "clients"
transformers:
- name: "Template"
params:
column: "name"
template: 'UAT Client {{- .GetColumnValue "id" -}}'
validate: true
- schema: "public"
name: "projects"
transformers:
- name: "Template"
params:
column: "name"
template: 'UAT Project {{- .GetColumnValue "id" -}}'
validate: true
- name: "Template"
params:
column: "description"
template: 'Masked UAT project generated from production project {{- .GetColumnValue "id" -}}'
validate: true
```
The output does not need to be pretty. It needs to be safe and still useful for testing.
## [Treat Free Text as Guilty Until Reviewed](#treat-free-text-as-guilty-until-reviewed)
Free-text fields are where sensitive data hides. A column called `comment` or `description` might contain customer names, internal URLs, credentials, snippets from support tickets, error logs, or copied report content.
I treat these as sensitive by default:
```
comments
notes
descriptions
issue text
activity logs
error messages
scan output
support messages
custom fields
AI-generated explanations
manual testing notes
```
Example rules:
```
- schema: "public"
name: "issue_comments"
transformers:
- name: "Template"
params:
column: "comment"
template: 'Masked UAT comment for issue {{- .GetColumnValue "issue_id" -}}'
validate: true
- schema: "public"
name: "issues"
transformers:
- name: "Template"
params:
column: "title"
template: 'UAT Issue {{- .GetColumnValue "id" -}}'
validate: true
- name: "Template"
params:
column: "description"
template: 'Masked UAT issue description for issue {{- .GetColumnValue "id" -}}'
validate: true
- name: "Template"
params:
column: "recommendation"
template: 'Masked remediation guidance for UAT validation.'
validate: true
```
Again, the aim is not literary quality. The aim is to keep screens, filters, counts, permissions, and workflows realistic without bringing production content along for the ride.
## [Drop Runtime Secrets Completely](#drop-runtime-secrets-completely)
Some tables should not be masked. They should be empty.
Auth tokens, sessions, API keys, password resets, OAuth credentials, webhook secrets, and invite tokens usually have no business entering UAT.
```
- schema: "public"
name: "tokens"
query: "select * from public.tokens where false"
```
That keeps the table in the dump but writes zero rows.
I use this pattern for tables like:
```
tokens
sessions
refresh_tokens
password_reset_tokens
email_verification_tokens
oauth_credentials
webhook_secrets
api_keys
```
Caution
The rule of thumb is simple: if the value can authenticate, authorize, impersonate, call an API, or access a file, it should not be restored into UAT.
## [Copy Lookup Tables Carefully](#copy-lookup-tables-carefully)
Not every table needs a rule. Static lookup tables often define application behavior rather than customer data.
These are usually safe to copy as-is after a quick review:
```
roles
severity
guidelines
success_criteria
country
state
project_status
testing_status
reporting_status
assistive_technology
project_environment
project_platform
```
The review matters because teams sometimes mix customer-specific configuration into tables that look like harmless lookup data.
When I classify a schema, I use these buckets:
| Bucket | Meaning | Action |
| --- | --- | --- |
| Sensitive data | PII, customer content, secrets, or production URLs | Mask columns |
| Dangerous runtime data | Tokens, sessions, credentials, secrets | Skip rows |
| Reference data | Static application lookup data | Copy as-is |
| Mixed data | Config plus customer-specific content | Mask selectively |
| Unknown | Not reviewed yet | Treat as sensitive |
The last row is important. Unknown does not mean safe.
## [Validate Before You Restore Anything](#validate-before-you-restore-anything)
Before creating a dump or restoring into UAT, validate the config from the runner container:
```
greenmask --config /config/greenmask.yml validate --data --diff --transformed-only
```
Look at the transformed output. Do not treat validation as a green checkmark you blindly accept. You are looking for evidence that the risky fields changed:
```
emails
names
client names
project names
URLs
comments
issue text
tokens
code fields
free-text descriptions
```
Only after that do I run the first dump:
```
greenmask --config /config/greenmask.yml dump
```
At this point production is still only being read. UAT has not been touched. That separation is useful because it lets you prove the masking side before allowing a destructive restore.
Then restore into UAT:
```
greenmask --config /config/greenmask.yml restore latest
```
Before a manual restore, I still check the config like a person who enjoys sleeping:
```
restore.pg_restore_options.dbname points to app_uat
restore.pg_restore_options.dbname does not point to app_prod
```
## [Add Post-Restore Checks](#add-post-restore-checks)
A refresh pipeline should not end at "restore succeeded." Restores can succeed while masking is incomplete.
After the restore, run SQL checks against UAT:
```
SELECT COUNT(*) FROM users
WHERE email !~ '^uat-user-[0-9]+@example\.test$';
```
```
SELECT COUNT(*) FROM tokens;
```
```
SELECT COUNT(*) FROM clients
WHERE name NOT LIKE 'UAT Client %';
```
```
SELECT COUNT(*) FROM projects
WHERE name NOT LIKE 'UAT Project %';
```
```
SELECT COUNT(*) FROM issue_comments
WHERE comment NOT LIKE 'Masked UAT comment%';
```
```
SELECT COUNT(*) FROM urls
WHERE url NOT LIKE 'https://uat-target.example.test/%';
```
Each query should return:
```
0
```
Add checks for your own sensitive categories:
```
real customer emails
phone numbers
access tokens
refresh tokens
API keys
webhook secrets
production URLs
uploaded file paths
payment identifiers
OAuth credentials
third-party integration secrets
```
Warning
Schema changes are the reason these checks matter. A new sensitive column can be added to production later and silently copied into UAT unless the pipeline has a second line of defense.
## [Keep the UAT Application Isolated Too](#keep-the-uat-application-isolated-too)
A masked database is only one part of UAT safety. The application runtime also needs to be separate.
Example:
```
NODE_ENV=uat
APP_URL=https://uat.example.com
DATABASE_URL=postgresql://uat_user:uat_password@app-uat-postgres:5432/app_uat
```
Do not reuse production integrations for:
```
email providers
file storage
payment gateways
scan APIs
analytics
webhooks
third-party integrations
```
UAT should not send real customer emails, trigger production webhooks, charge real payments, write to production storage, or report analytics into the production stream. If the database is disposable but the integrations are live, the environment is not actually safe.
## [Schedule It Only After Manual Runs](#schedule-it-only-after-manual-runs)
Once the manual flow works, create a scheduled job in Dokploy:
1. Open Schedule Jobs.
2. Create a new job.
3. Select the `greenmask-runner` container.
4. Use this command:
```
/bin/sh -lc 'greenmask --config /config/greenmask.yml dump && greenmask --config /config/greenmask.yml restore latest'
```
A daily 2 AM server-time schedule looks like this:
```
0 2 * * *
```
I do not enable the schedule on day one. I run the job manually, review the output, inspect UAT, and repeat that for a few cycles. Once the process is boring, then it can be automatic.
My rollout checklist is usually:
1. Create a separate UAT database.
2. Add the Greenmask runner container.
3. Add the Greenmask config.
4. Classify sensitive tables.
5. Add masking rules.
6. Validate masking output.
7. Run the first masked dump.
8. Restore into a disposable UAT database.
9. Run SQL safety checks.
10. Point the UAT app to the UAT database.
11. Test login and core UAT flows.
12. Run the refresh manually for a few cycles.
13. Enable the Dokploy scheduled job.
## [The Guardrails I Would Not Skip](#the-guardrails-i-would-not-skip)
Use a read-only production user. Greenmask only needs `SELECT` for the dump. The production user should not be able to write, truncate, drop, alter, or create.
Keep restore credentials UAT-only. The restore user should not even be valid against production.
Make the names obvious. Prefer `app_prod`, `app_uat`, `app-prod-postgres`, and `app-uat-postgres` over names like `db`, `main`, `default`, or `postgres`.
Do not reuse production integrations. Use sandbox credentials for email, storage, payments, OAuth apps, webhooks, analytics, logging, and external APIs.
Check masking after every restore. Greenmask config is not a substitute for verification, especially as the schema evolves.
The safest model is:
```
Production is read-only input.
Greenmask is the transformation boundary.
UAT is disposable output.
```
If those three statements stay true, the refresh pipeline becomes predictable enough to run on a schedule without turning every refresh into a production risk.
[contact](https://criston.dev/cdn-cgi/l/email-protection#3a5955544e5b594e7a594853494e5554145e5f4c) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Writing | Criston Mascarenhas
url: https://criston.dev/writing
description: Articles and notes on software engineering, product craft, and developer tools.
---
Writing
Writing
Articles, notes, and essays on engineering, developer tools, accessibility, and product craft.
## On this site
- [**A Safe Masked UAT Refresh Pipeline with Dokploy and Greenmask**How I set up a repeatable PostgreSQL UAT refresh flow that reads production, masks sensitive data with Greenmask, and restores only into a disposable UAT database.PostgreSQL · Dokploy · Greenmask · infrastructureJun 18, 2026
12 min](https://criston.dev/writing/safe-masked-uat-refresh-pipeline-dokploy-greenmask)
- [**Building a Production-Grade Accessibility Scanning Platform**An architectural deep-dive into A11yNow — the distributed web accessibility auditing backend I built at BarrierBreak. Browser pooling, distributed scheduling, multi-auth, error resilience, and a 600MB Docker image.accessibility · architecture · TypeScript · infrastructureJun 16, 2026
13 min](https://criston.dev/writing/building-a-production-grade-accessibility-scanning-platform)
- [**Building a Scalable Browser Automation Platform for Accessibility Scanning**Page pooling, LRU-cached browser instances, multi-auth, stealth, and adblock — all in one Node.js service. A deep-dive into the browser automation layer I built for A11yNow at BarrierBreak.accessibility · browser automation · Playwright · architectureJun 16, 2026
12 min](https://criston.dev/writing/scaling-browser-automation-for-accessibility-scanning)
- [**Why We Built Our Own Accessibility Engine (And What "Accuracy" Really Means)**Most accessibility scanners sort the world into violations and passes. We think that's the wrong model — and here's the thinking we built around instead.accessibility · WCAG · engineeringJun 15, 2026
3 min](https://criston.dev/writing/why-we-built-our-own-accessibility-engine)
## From Medium
Loading posts…
[contact](https://criston.dev/cdn-cgi/l/email-protection#a3c0cccdd7c2c0d7e3c0d1cad0d7cccd8dc7c6d5) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Uses | Criston Mascarenhas
url: https://criston.dev/uses
description: Senior software engineer building accessibility platforms, developer tools, and shipped products — browser automation, multi-tenant SaaS, native apps, and libraries. TypeScript, React, Node.js, PostgreSQL, Swift, and Rust.
---
Uses
Uses
Hardware, software, and small utilities I use to design, build, and ship.
## Hardware
The machines I build and test on.
- [**MacBook Air**
M2 · 16 GB memory · the everyday machine](https://www.apple.com/macbook-air/)
- [**MacBook Pro**
M4 Pro · 24 GB memory](https://www.apple.com/macbook-pro/)
- [**Samsung Galaxy S24 Ultra**
Android device for daily use and app testing](https://www.samsung.com/galaxy-s24-ultra/)
## Code & AI
Editors, IDEs, and the assistants in the loop.
- [**Visual Studio Code**
Primary code editor](https://code.visualstudio.com/)
- [**Claude**
Thinking, research, and coding assistant](https://claude.ai/)
- [**Codex**
Coding agent for building and maintaining software](https://developers.openai.com/codex/)
- [**Android Studio**
Android development and device tooling](https://developer.android.com/studio)
- [**Xcode**
macOS and Apple platform development](https://developer.apple.com/xcode/)
- [**IntelliJ IDEA**
JVM projects and deeper code navigation](https://www.jetbrains.com/idea/)
## Terminal & infrastructure
The shell, services, and debugging tools underneath the work.
- [**Ghostty**
Primary terminal emulator](https://ghostty.org/)
- [**Zsh**
Interactive shell](https://www.zsh.org/)
- [**Oh My Zsh**
Shell configuration, plugins, and themes](https://ohmyz.sh/)
- [**Docker**
Local services, containers, and reproducible environments](https://www.docker.com/)
- [**PostgreSQL**
The default relational database](https://www.postgresql.org/)
- [**DBeaver**
Cross-database exploration and administration](https://dbeaver.io/)
- [**MongoDB Compass**
Visual MongoDB exploration](https://www.mongodb.com/products/tools/compass)
- [**pgAdmin**
PostgreSQL administration](https://www.pgadmin.org/)
- [**Insomnia**
A focused API client](https://insomnia.rest/)
- [**ngrok**
Temporary public tunnels for local services](https://ngrok.com/)
- [**Tailscale**
Private networking between devices](https://tailscale.com/)
## Design & craft
Interface work, visuals, screenshots, and occasional 3D or hardware detours.
- [**Figma**
Interface design and collaboration](https://www.figma.com/)
- [**Pixelmator Pro**
Fast image editing on macOS](https://www.pixelmator.com/pro/)
- [**Blender**
3D modelling and rendering](https://www.blender.org/)
- [**FreeCAD**
Parametric 3D modelling](https://www.freecad.org/)
- [**KiCad**
PCB design and electronics work](https://www.kicad.org/)
- [**Shottr**
Screenshots, annotation, and measurement](https://shottr.cc/)
- [**Responsively**
Responsive interface testing across viewports](https://responsively.app/)
## Browsers
Daily browsing and the slightly excessive test matrix.
- [**Google Chrome**
Primary Chromium browser](https://www.google.com/chrome/)
- [**Chrome Canary**
Early browser changes and compatibility testing](https://www.google.com/chrome/canary/)
- [**Firefox Developer Edition**
Firefox testing and developer tools](https://www.mozilla.org/firefox/developer/)
## Workflow
Small utilities and places where the rest of the day happens.
- [**Raycast**
Launcher, snippets, quick links, and tiny automations](https://www.raycast.com/)
- [**Notion**
Project notes and longer-lived documents](https://www.notion.so/)
- [**Obsidian**
Local notes and connected thinking](https://obsidian.md/)
- [**Spotify**
The background process that rarely gets killed](https://www.spotify.com/)
[contact](https://criston.dev/cdn-cgi/l/email-protection#fe9d91908a9f9d8abe9d8c978d8a9190d09a9b88) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---
---
title: Building a Scalable Browser Automation Platform for Accessibility Scanning | Criston Mascarenhas
url: https://criston.dev/writing/scaling-browser-automation-for-accessibility-scanning
description: Page pooling, LRU-cached browser instances, multi-auth, stealth, and adblock — all in one Node.js service. A deep-dive into the browser automation layer I built for A11yNow at BarrierBreak.
---
Building a Scalable Browser Automation Platform for Accessibility Scanning
accessibility · browser automation · Playwright · architecture · TypeScript
# Building a Scalable Browser Automation Platform for Accessibility Scanning
Page pooling, LRU-cached browser instances, multi-auth, stealth, and adblock — all in one Node.js service. A deep-dive into the browser automation layer I built for A11yNow at BarrierBreak.
By [Criston Mascarenhas](https://criston.dev/about) · June 16, 2026 · 12 min read
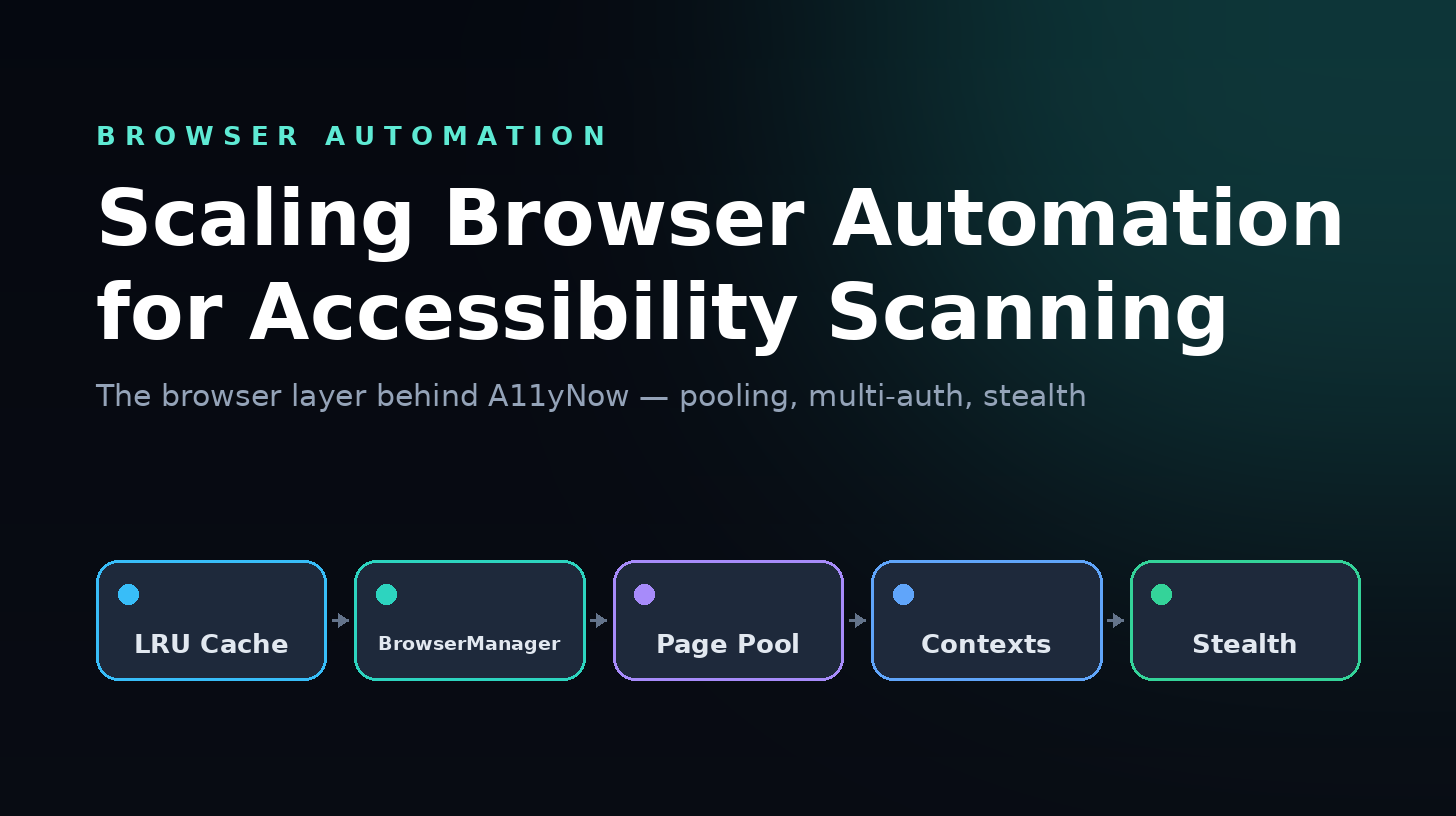
Automated accessibility testing requires real browsers. The WCAG spec cares about the rendered DOM, computed styles, and layout — things you can't get from a `curl` request. But running headless browsers at scale is notoriously painful: memory leaks, zombie processes, flaky CDP connections, and the ever-present risk of OOM kills.
This post covers the browser automation layer of **A11yNow** — the subsystem I built at BarrierBreak to manage Chromium, Firefox, and WebKit instances across hundreds of concurrent scans without falling over. Every pattern here was forged in production fire.
## [1. The two-layer pooling architecture](#1-the-two-layer-pooling-architecture)
There are two layers of resource pooling: browser instances (heavy, \~300MB each) and pages (light, \~10MB each). They're managed differently because they have different costs and lifetimes.
```
┌────────────────────────────────────────────────────────┐
│ CoreScannerService │
│ │
│ ┌──────────────────────────────────────────────────┐ │
│ │ LRU Cache: BrowserManager instances │ │
│ │ Key: projectId:browserType:device │ │
│ │ Max: 12, TTL: 10 min │ │
│ └────────────────────────┬─────────────────────────┘ │
│ │ │
│ ┌────────────────────────▼─────────────────────────┐ │
│ │ BrowserManager (per project) │ │
│ │ │ │
│ │ ┌────────────────────────────────────────────┐ │ │
│ │ │ Active Page Pool (max 5) │ │ │
│ │ │ Request Queue (max 20, 120s) │ │ │
│ │ └────────────────────────────────────────────┘ │ │
│ └──────────────────────────────────────────────────┘ │
└────────────────────────────────────────────────────────┘
```
### [Why per-project?](#why-per-project)
Different projects need different browser configurations. Project A might test a public marketing site (no auth, desktop only). Project B might test an authenticated admin dashboard (cookie auth, mobile viewport, ad blocking). Sharing one browser between them would mean constantly tearing down and rebuilding browser contexts — roughly as expensive as launching a new browser.
Instead, each project gets its own browser manager with a fixed configuration. It lives in an LRU cache so inactive projects get evicted, freeing memory for active ones.
## [2. LRU cache with safe disposal](#2-lru-cache-with-safe-disposal)
The cache is a standard `lru-cache` instance with one production-hardened twist — the `dispose` handler:
```
this.projectBrowserManagers = new LRUCache({
max: parseInt(process.env.BROWSER_POOL_MAX_SIZE || '12', 10),
ttl: 1000 * 60 * parseInt(process.env.BROWSER_POOL_TTL_MINUTES || '10', 10),
ttlAutopurge: true,
updateAgeOnGet: true, // Reset TTL on access — prevents mid-scan eviction
dispose: (value, key) => {
// LRUCache's dispose is synchronous, but shutdown is async.
// Track the promise so graceful shutdown can await it.
const p = (async () => {
try {
logger.info('LRU evicting browser manager, shutting down', { projectId: key });
await value.shutdown();
} catch (error) {
logger.error('Error shutting down during LRU eviction', { projectId: key, error });
} finally {
this.pendingDisposals.delete(p);
}
})();
this.pendingDisposals.add(p);
},
});
```
Three details matter here:
1. **`updateAgeOnGet: true`** — Every `acquirePage()` call touches the cache entry, resetting its TTL. A project actively receiving scan requests won't have its browser evicted mid-scan.
2. **`max` is the real limit, not `ttl`** — TTL auto-purge cleans stale browsers, but `max: 12` is the hard cap. The 13th project gets the least-recently-used entry evicted.
3. **`pendingDisposals` set** — The `dispose` callback is synchronous, but `browser.close()` is async. If the process receives SIGTERM during a disposal, the graceful-shutdown handler calls `awaitPendingDisposals()` to avoid leaking browser processes.
### [Concurrent creation guard](#concurrent-creation-guard)
A subtle race: two scans for the same project arrive simultaneously. Without a guard, both would see a cache miss and create two browser-manager instances:
```
private getProjectBrowserManager(projectId, browserType, devicePreset) {
const cacheKey = `${projectId}:${browserType}:${devicePreset || 'desktop'}`;
if (this.projectBrowserManagers.has(cacheKey)) {
return Promise.resolve(this.projectBrowserManagers.get(cacheKey)!);
}
// Check for an in-flight creation promise
if (this.projectManagerPromises.has(cacheKey)) {
return this.projectManagerPromises.get(cacheKey)!;
}
const creationPromise = (async () => {
try {
const browserConfig = await this.buildBrowserConfig(projectId, ...);
const manager = new BrowserManager(browserConfig);
this.projectBrowserManagers.set(cacheKey, manager);
return manager;
} finally {
this.projectManagerPromises.delete(cacheKey);
}
})();
this.projectManagerPromises.set(cacheKey, creationPromise);
return creationPromise;
}
```
The first caller creates the promise and stores it in `projectManagerPromises`. Any subsequent caller before the promise resolves gets the same promise. Once resolved, the cache has the entry and the promise-map entry is cleaned.
## [3. Page pooling with request queuing](#3-page-pooling-with-request-queuing)
Each browser manager keeps up to 5 active pages. When a scan needs a page and the pool is full, it doesn't throw — it queues:
```
async acquirePage(): Promise {
this.lastActivityTime = Date.now();
// Under capacity: create a new page
if (this.activePagesSet.size < this.maxPoolSize) {
const browser = await this.getBrowser();
const pageContext = await browser.newContext(this.buildContextOptions());
const page = await pageContext.newPage();
page.on('close', () => {
pageContext.close().catch(e =>
logger.warn('Failed to close browser context', { error: e.message })
);
});
this.activePagesSet.add(page);
const blocker = await this.getAdBlocker();
if (blocker) {
await blocker.enableBlockingInPage(page);
}
return page;
}
// Pool full — queue with timeout
return new Promise((resolve, reject) => {
const timeout = setTimeout(() => {
const idx = this.pageRequestQueue.findIndex(req => req.timeout === timeout);
if (idx !== -1) this.pageRequestQueue.splice(idx, 1);
reject(new ScanError(
ErrorCode.BROWSER_LAUNCH_FAILED,
`Timed out waiting for available page (${this.maxQueueWaitTimeMs / 1000}s)`,
false
));
}, this.maxQueueWaitTimeMs);
this.pageRequestQueue.push({ resolve, reject, timestamp: Date.now(), timeout });
});
}
```
### [Queue processing is event-driven + periodic](#queue-processing-is-event-driven--periodic)
When a page is released, the queue is processed immediately:
```
async releasePage(page: Page): Promise {
this.activePagesSet.delete(page);
await this.closePage(page);
// Don't wait for the 5s timer — process now
this.processQueue();
}
```
But there's also a fallback 5-second interval timer. Why both? If a page release triggers an error during close, `processQueue()` might not be called. The interval ensures queued requests don't starve.
`processQueue()` itself is simple: dequeue the oldest request, clear its timeout, call `acquirePage()` (which will now have capacity), and resolve/reject the promise:
```
private processQueue(): void {
if (this.isShuttingDown || this.pageRequestQueue.length === 0 ||
this.activePagesSet.size >= this.maxPoolSize) {
return;
}
const request = this.pageRequestQueue.shift()!;
clearTimeout(request.timeout);
this.acquirePage()
.then(page => request.resolve(page))
.catch(error => request.reject(error));
}
```
## [4. Page isolation via browser contexts](#4-page-isolation-via-browser-contexts)
Every page gets its own Playwright `BrowserContext` — not just its own page. This means:
- **Isolated cookies, localStorage, and sessionStorage** — one scan's login state can't leak into another.
- **Per-page viewport, device scale, and user agent** — mobile scan contexts use `isMobile: true` and touch emulation, desktop contexts don't.
- **Automatic cleanup** — the page's `close` event auto-closes its context.
```
private buildContextOptions(): Record {
const opts = {
viewport: this.config.viewport,
deviceScaleFactor: this.config.deviceScaleFactor ?? 1,
javaScriptEnabled: true,
ignoreHTTPSErrors: true,
};
if (this.config.userAgent) opts.userAgent = this.config.userAgent;
// Browser-type awareness
if (this.browserType === 'firefox') {
// Firefox doesn't support isMobile/hasTouch emulation
} else if (this.browserType === 'webkit' && process.platform === 'linux') {
// Linux WebKit doesn't support touch/mobile emulation
} else {
opts.isMobile = this.config.isMobile ?? false;
}
if (!(this.browserType === 'webkit' && process.platform === 'linux')) {
opts.hasTouch = this.config.hasTouch ?? false;
}
return opts;
}
```
Note
The browser-type gating avoids runtime errors. Setting `isMobile` on Firefox or `hasTouch` on Linux WebKit would cause Playwright to throw — so those flags are silently skipped with a warning.
## [5. Ad blocking: shared engine, per-page enablement](#5-ad-blocking-shared-engine-per-page-enablement)
Ad and cookie-banner blocking uses `@ghostery/adblocker-playwright`. The engine is a 30MB parsed filter list — creating one per page would be catastrophic. So it's shared at the module level:
```
// Module-level cache — one engine per filter list combination
const SHARED_BLOCKER_CACHE = new Map>();
private async getAdBlocker(): Promise {
const filterUrls: string[] = [];
if (this.blockAds) filterUrls.push('https://easylist.to/easylist/easylist.txt');
if (this.blockCookieBanners) {
filterUrls.push('https://secure.fanboy.co.nz/fanboy-cookiemonster.txt');
filterUrls.push('https://secure.fanboy.co.nz/fanboy-annoyance.txt');
}
if (this.blockTrackers) filterUrls.push('https://easylist.to/easylist/easyprivacy.txt');
if (filterUrls.length === 0) return null;
const cacheKey = [...filterUrls].sort().join('|');
let cached = SHARED_BLOCKER_CACHE.get(cacheKey);
if (!cached) {
cached = PlaywrightBlocker.fromLists(fetch, filterUrls).catch(error => {
SHARED_BLOCKER_CACHE.delete(cacheKey); // Don't cache failures
throw error;
});
SHARED_BLOCKER_CACHE.set(cacheKey, cached);
}
return cached;
}
```
The engine is then enabled per-page via `enableBlockingInPage(page)`. This means 20 concurrent pages for the same project share one 30MB filter engine, not 600MB.
## [6. Multi-auth: five strategies, one interface](#6-multi-auth-five-strategies-one-interface)
Authenticated scanning supports five strategies through a unified config:
| Strategy | Config shape |
| --- | --- |
| basic | `{ type: 'basic', username, password }` |
| bearer | `{ type: 'bearer', token }` |
| cookie | `{ type: 'cookie', cookies: [{ name, value }] }` |
| ntlm | `{ type: 'ntlm', username, password }` |
| ui | `{ type: 'ui', usernameSelector, passwordSelector }` or `{ type: 'ui', steps: [...] }` |
Each config is validated before use:
```
private validateAuthConfig(config: unknown): boolean {
const type = (config as any)?.type;
switch (type) {
case 'basic':
case 'ntlm':
return typeof config.username === 'string'
&& typeof config.password === 'string';
case 'bearer':
return typeof config.token === 'string';
case 'cookie':
return Array.isArray(config.cookies)
&& config.cookies.every(c => c.name && c.value);
case 'ui':
return (
(config.usernameSelector && config.passwordSelector) ||
(Array.isArray(config.steps) && config.steps.length > 0)
);
default:
return false;
}
}
```
### [Session caching via Redis](#session-caching-via-redis)
After a successful login, the browser state (cookies, localStorage) is saved to Redis with a TTL:
```
async authenticate(page, url, authConfig, sessionId) {
// 1. Try saved session first
if (sessionId) {
const hasSession = await authService.hasAuthSession(sessionId);
if (hasSession) {
const restored = await authService.restoreAuthSession(page, sessionId);
if (restored.success) {
await authService.refreshAuthSession(sessionId); // Extend TTL
return { success: true, page: restored.page };
}
// Session stale — delete and fall through
await authService.deleteAuthSession(sessionId);
}
}
// 2. Fresh authentication
await page.goto('about:blank'); // Clean slate
const result = await authService.authenticate(page, url, authConfig);
if (!result.success) {
return { success: false, page, error: { code: 'AUTH_FAILED', ... } };
}
// 3. Cache the session for next scan
if (sessionId) {
await authService.saveAuthSession(result.page, sessionId);
}
return { success: true, page: result.page };
}
```
Note
This matters because a project might run 50 scheduled scans in a batch. Without session caching, every single scan would re-login — triggering rate limits, audit logs, and potentially MFA prompts.
## [7. Stealth: evading bot detection](#7-stealth-evading-bot-detection)
Many sites block headless browsers. For local Chromium, I use `playwright-extra` with the stealth plugin:
```
// Applied once at browser-manager construction
if (this.browserType === 'chromium') {
playwrightExtraChromium.use(stealth());
}
// Later, at launch time:
if (this.browserType === 'chromium') {
browser = await playwrightExtraChromium.launch({
headless: this.config.headless,
args: ['--no-sandbox', '--disable-setuid-sandbox',
'--disable-dev-shm-usage', '--disable-gpu'],
});
}
```
The stealth plugin patches `navigator.webdriver`, `navigator.plugins`, `navigator.languages`, `window.chrome`, and other fingerprints that sites use to detect automation. For remote Browserless deployments, stealth isn't needed — Browserless itself presents as a real browser.
## [8. Error resilience: discriminated errors + smart retry](#8-error-resilience-discriminated-errors--smart-retry)
Not all errors should be retried. A `401 Unauthorized` won't fix itself. An `ECONNRESET` on the CDP connection probably will. The system uses discriminated scan errors:
```
type ErrorCode =
| 'BROWSER_LAUNCH_FAILED' // Retryable: browser processes crash
| 'PAGE_LOAD_FAILED' // Retryable: transient network issues
| 'AUTH_FAILED' // NOT retryable: bad credentials
| 'SCAN_TIMEOUT' // Retryable: slow page, might load next time
| 'SCAN_CANCELLED' // NOT retryable: user-requested
| 'ADBLOCKER_INIT_FAILED' // Depends: retryable if network, not if config
| 'UNKNOWN_ERROR'; // Conservative: NOT retryable
```
The retry handler uses exponential backoff with 30% jitter:
```
new RetryHandler({
maxRetries: 3,
baseDelay: 1000, // 1s
maxDelay: 8000, // 8s (1s × 2^3)
retryableErrors: [
ErrorCode.BROWSER_LAUNCH_FAILED,
ErrorCode.PAGE_LOAD_FAILED,
ErrorCode.SCAN_TIMEOUT
]
});
```
At the browser-launch level, there's a separate retry loop with configuration fallbacks:
```
// Browser launch retry loop with config fallbacks
while (retryCount <= 2) {
try {
const browser = await playwrightExtraChromium.launch({
headless: this.config.headless,
args: chromiumArgs,
timeout: launchTimeout,
});
return browser;
} catch (error) {
retryCount++;
if (retryCount === 2 && this.browserType === 'chromium') {
// Final attempt: try the newer headless mode
chromiumArgs.push('--headless=new');
}
await sleep(2000 * Math.pow(2, retryCount - 1));
}
}
```
Tip
The `--headless=new` fallback is important — some sites detect and block the old headless mode, but the newer mode (which uses the native browser UI under the hood) often passes through.
## [9. Remote Browserless: CDP with protocol fallback](#9-remote-browserless-cdp-with-protocol-fallback)
In production, browsers run on a separate Browserless cluster. The connection code handles both CDP (Browserless native) and standard Playwright WebSocket protocols:
```
private async connectToRemoteBrowser(endpoint: string): Promise {
const wsEndpoint = endpoint
.replace('http://', 'ws://')
.replace('https://', 'wss://');
for (let retry = 0; retry <= 3; retry++) {
try {
// Try CDP first (Browserless speaks this natively)
const browser = await playwrightChromium.connectOverCDP(wsEndpoint, { timeout: 30000 });
this.setupBrowserListeners(browser);
return browser;
} catch (cdpError) {
const msg = cdpError.message;
if (msg.includes('Protocol error') || msg.includes('undefined')) {
// Not Browserless — try standard Playwright connect
try {
const browser = await playwrightChromium.connect(wsEndpoint, { timeout: 30000 });
this.setupBrowserListeners(browser);
return browser;
} catch (pwError) {
throw cdpError; // Both failed — throw original
}
}
throw cdpError;
}
}
}
```
The retry loop (3 attempts with exponential backoff) handles transient connection failures. The disconnection listener cleans up state:
```
browser.on('disconnected', () => {
logger.warn(`Browser disconnected`, {
endpoint: this.lastRemoteEndpoint,
activePages: this.activePagesSet.size,
queueLength: this.pageRequestQueue.length,
});
if (this.browser === browser) {
this.browser = undefined; // Force reconnection on next acquirePage
}
});
```
## [10. Idle detection: auto-shutdown inactive browsers](#10-idle-detection-auto-shutdown-inactive-browsers)
A browser with no active pages for 5 minutes gets shut down:
```
constructor(config, maxPoolSize = 5, idleTimeoutMs = 300000) {
this.idleCheckTimer = setInterval(
() => this.checkIdleTimeout(idleTimeoutMs),
60000 // Check every minute
);
this.idleCheckTimer.unref(); // Don't keep the process alive
}
private checkIdleTimeout(idleTimeoutMs: number): void {
if (this.isShuttingDown || this.activePagesSet.size > 0) return;
const idleTime = Date.now() - this.lastActivityTime;
if (idleTime > idleTimeoutMs && this.browser) {
const browserToClose = this.browser;
this.browser = undefined; // Clear immediately
browserToClose.close()
.then(() => logger.info('Closed idle browser'))
.catch(err => logger.error('Failed to close idle browser', { err }));
}
}
```
The `.unref()` on the timer is important — it prevents the idle check from keeping the entire Node.js process alive if there's nothing else running.
## [Key takeaways](#key-takeaways)
1. **Two-layer pooling (browser LRU + page queues) matches the cost structure.** Browsers are expensive and shared across scans; pages are cheap and recycled within a scan batch.
2. **LRU dispose must handle async.** Browser closing is async, but the LRU's `dispose` is sync. Track shutdown promises in a `Set` and await them during graceful shutdown.
3. **A module-level adblocker cache saves \~30MB × N.** One engine per filter config, shared across all pages via `enableBlockingInPage()`.
4. **Auth sessions in Redis eliminate re-logins across batch scans** — critical for rate-limited or MFA-protected sites.
5. **Error discrimination enables selective retry.** Don't retry `AUTH_FAILED` (wrong password); do retry `BROWSER_LAUNCH_FAILED` (CDP hiccup).
6. **CDP-first, Playwright-fallback connection** handles both Browserless and generic Playwright servers without configuration flags.
[contact](https://criston.dev/cdn-cgi/l/email-protection#31525e5f455052457152435842455e5f1f555447) [github](https://github.com/crstnmac) [linkedin](https://www.linkedin.com/in/devcriston/)
© 2026 Criston Mascarenhas
---